A personality assessment can look more predictive in a restricted sample because the people studied do not represent the full range of scores or circumstances in the population of interest. The word predictive is also doing a lot of work: a correlation observed among selected employees, volunteers, or high scorers may not transfer to applicants, a wider community, or a different decision. In the usual case, restricting the range of an assessment score or outcome reduces the visible correlation because there is less variation to compare. But the size and direction of the effect depend on how the sample was selected, which variable was restricted, the shape of the relationship, and the reliability of the measures. A responsible report should therefore show the sample, the intended population, the observed validity evidence, and the uncertainty around any correction rather than presenting one adjusted number as a universal fact.
Start with the decision behind the prediction
Imagine reading a validation summary for a personality assessment used in a workplace. It says that the assessment is related to a performance measure among current employees. You want to know whether that evidence applies to people who have not yet been hired. The first question is not whether the reported coefficient sounds large. It is whether the study group and the decision group have comparable variation, selection rules, measures, and circumstances.
A predictive claim links an assessment result to a later or external outcome. In a report, that outcome might be job performance, training completion, turnover, or another defined criterion. A validity coefficient is a numerical description of the relationship for a particular claim and sample. It does not mean that the assessment causes the outcome, identifies a person's fixed nature, or predicts every individual equally. The American Psychological Association defines validity in terms of evidence supporting the adequacy and appropriateness of conclusions drawn from an assessment, so the conclusion must stay tied to its intended use.
Restriction of range matters because a sample may be unusually alike on the assessment, the outcome, or both. A group of people who passed an earlier screen is different from the full applicant pool. A group of experienced employees is different from people at the start of training. If the report moves from the first group to the second without explaining that difference, its predictive language may be broader than its evidence.
What restricted range means in plain language
Range restriction means that the observed data cover only a narrower spread than the population or decision context being discussed. A simple example is a study of assessment scores among people already admitted to a selective program. If the admission process removed most of the lower scores, the study cannot compare the full pattern that existed before admission. The same issue can arise at the other end of a scale or through a narrow band of results created by a screening rule.
The reason this can affect prediction is straightforward. A correlation uses variation in two variables to describe how they move together. When one variable has little variation, there are fewer score differences with which to detect a relationship. An open statistics text from Kennesaw State University demonstrates this by showing a relationship that becomes smaller after the lower part of one variable is removed. That demonstration is useful for intuition, not a universal numerical rule: real data may be nonlinear, unevenly distributed, or selected in more than one way.
Restriction is not the same as a small sample. A small study can include a broad range, and a large study can be tightly clustered. Sample size affects uncertainty and statistical power; range restriction affects what variation is available to study. They can occur together, but they answer different questions. A report should tell you both how many people were included and how dispersed their relevant scores were.
Why the same assessment can look weaker or stronger
Suppose an assessment score is related to a performance criterion in a broad applicant pool. After hiring, the remaining employees may have been selected using that assessment, another test, an interview, prior experience, or a combination. Their scores can be more similar than the applicants' scores. The relationship observed among employees may then be smaller than the relationship in the applicant pool, because the study no longer contains the original spread.
This is the familiar attenuation story, but it needs a boundary. Range restriction often reduces the magnitude of an observed correlation when the selection process removes part of the relevant range. It does not guarantee that every restricted sample produces a smaller coefficient. The distribution, selection mechanism, measurement error, nonlinear pattern, and whether the restriction concerns the predictor or the criterion all matter. The teaching discussion of range restriction also notes that its effects on validity, reliability, and power depend on the score distribution and selection procedure.
The reverse mistake is also possible: treating a high coefficient in a narrow or unusually selected group as proof of broad usefulness. A compact cluster can make a few points, influential cases, or a particular selection rule matter greatly. A report reader should ask to see a scatterplot or other description of the data, not only a headline coefficient. If the observed relationship is based on a narrow slice, its generalizability is an open question, not a detail to fill in later.
Direct and indirect restriction are different
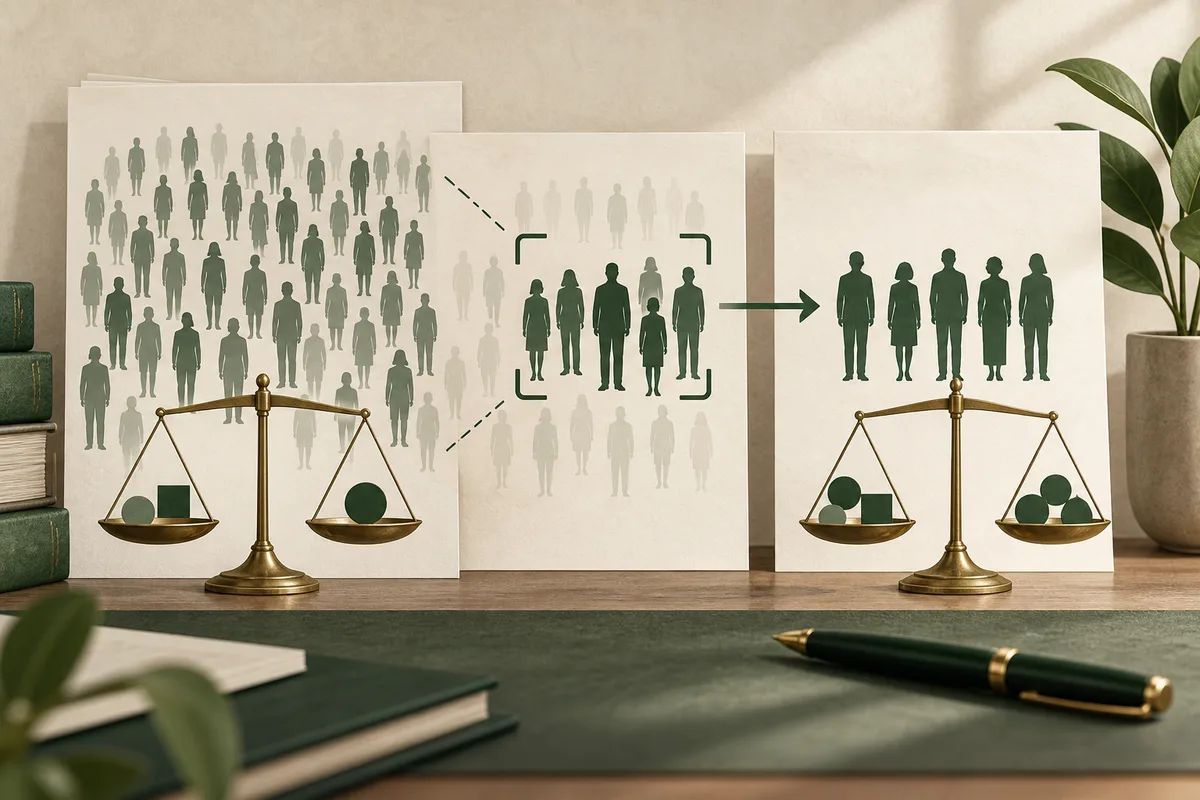
Direct restriction occurs when the assessment being evaluated is itself used to select the study group. For example, a study of hired employees may contain only people whose assessment results met a hiring rule. That process can remove part of the predictor's range before the outcome is measured.
Indirect restriction occurs when selection is based on another variable that is related to the assessment. An employer might select on an interview or prior experience, while researchers later study personality scores. The personality scores may still be less varied because they overlap with the selection variable. The effect is not automatic; it depends on how strongly the variables are related and how selective the process was.
This distinction changes what a reader should request. Ask what actually determined entry into the validation sample, not merely whether the personality assessment was administered. The 2023 Society for Industrial and Organizational Psychology article by Sackett and colleagues explains that range restriction is present when a validity sample has a smaller standard deviation than the applicant pool for which the predictor is proposed. It also describes why indirect restriction can matter in some circumstances and little in others.
A report that says only ‘validated on employees’ leaves out the mechanism that produced the employee sample. The useful follow-up is: selected from whom, using what information, and for which future decision?
Why correction is not a magic repair
Researchers can use range-restriction corrections to estimate what a relationship might have looked like in a less restricted population. A correction is a model-based adjustment, not a new observation. It needs information about the original and restricted distributions, the selection process, and the assumptions linking them. If those inputs are uncertain or come from an unrepresentative set of studies, the adjusted coefficient can be misleadingly precise.
This matters because corrected numbers are often presented as if they were the real validity. In their 2022 meta-analysis, Sackett, Zhang, Berry, and Lievens revisited common corrections in personnel selection research and concluded that widely used procedures had often overcorrected validity estimates. Their abstract reports that revised mean estimates were lower by roughly .10 to .20 points across the selection procedures they examined. That result concerns a specific research literature, not every personality assessment, but it is a clear warning against treating correction as automatic improvement.
The later practice article recommends using sample-specific information where possible and being cautious when the standard-deviation information is weak. Its conservative advice is especially useful to readers: an uncorrected result may be an underestimate, but an unsupported correction can be an overestimate. The honest report may therefore give the observed coefficient, describe the likely direction of restriction, show a sensitivity analysis, and state what cannot be established.
Separate range restriction from reliability
Reliability and range restriction are related but different. Reliability concerns the consistency or precision of a measure under specified conditions. Range restriction concerns the spread of observed scores in the sample. A restricted sample can make a reliability estimate look different, and measurement error can weaken a relationship, but correcting one issue does not automatically solve the other.
The distinction is practical. If a personality assessment has an observed relationship with a performance criterion, a reader needs to know how each measure was scored, how consistently it was measured, and whether the criterion itself was noisy. A supervisor rating, for example, may reflect several aspects of performance and may be less consistent than a tightly defined count. That does not make the personality assessment invalid; it changes the precision and interpretation of the claim.
The 2023 practice article advises correcting for reliability before applying a range-restriction correction when both are justified, because the reliability estimate may itself come from a restricted incumbent sample. This is technical guidance for researchers, not a calculation a report reader should perform from a single headline. The reader-level question is simpler: does the report identify the sources of measurement error and the assumptions used to adjust the result?
A worked reading example without invented scores
Consider a report that compares a personality assessment with later training performance. The researchers studied people who had already passed a screening process and completed the same training course. The report shows a positive association and calls the assessment predictive. You are considering whether to use the result for a new applicant pool that includes people who were not screened in the same way.
Read the evidence in layers. First, identify the predictor: was it a total score, a facet, a band, or a different format? Second, identify the criterion: what exactly counted as training performance, and when was it measured? Third, identify the sample path: who could enter the study, who was excluded, and what earlier decisions reduced the range? Fourth, compare the study population with the proposed use. The result may support a limited statement about association in the studied training group while offering weaker evidence for selection among a wider applicant pool.
Now imagine the report gives both an observed coefficient and a corrected estimate. Do not choose the larger number simply because it sounds more useful. Ask what distribution supplied the correction, whether the selection process was direct or indirect, and whether the corrected result is accompanied by an interval or sensitivity analysis. If those details are missing, the safer interpretation is not ‘the assessment has no value.’ It is ‘the report has not shown how far this estimate travels.’
This layered reading also protects against a common category error. A result can be useful for hypothesis generation, self-reflection, or a development conversation without being strong evidence for hiring or exclusion. The purpose of use sets the burden of evidence.
A practical checklist for the next report
Before relying on a predictive claim, look for these details:
1. The target population: Who is the claim meant to describe, and does the validation sample resemble that group?
2. The selection path: Which assessment, interview, experience rule, or other decision determined who entered the study?
3. The available range: Are predictor and outcome distributions reported, or is the reader asked to infer them from a coefficient?
4. The criterion: Is the outcome defined clearly, measured at the relevant time, and reliable enough for the decision?
5. The correction: Does the report distinguish observed from adjusted validity and explain the data and assumptions behind the adjustment?
6. The uncertainty: Are confidence or credibility intervals, between-study variation, subgroup evidence, and limitations visible?
7. The use: Is the evidence being used for reflection, coaching, development, selection, or a clinical decision? A general personality report should not be turned into a diagnosis.
If several answers are missing, lower the strength of the conclusion rather than filling the gaps with the report's most confident sentence. For a self-reflection or coaching use, treat the result as one structured source of information and check it against observed behavior and context. For a high-stakes workplace decision, ask for local validation that matches the proposed population and decision, along with safeguards for fair interpretation.
Sources and notes
- Revisiting meta-analytic estimates of validity in personnel selection: Addressing systematic overcorrection for restriction of range
Supports the distinction between observed and corrected validity and the warning that common range-restriction corrections can overestimate validity.
- Revisiting the design of selection systems in light of new findings regarding the validity of widely used predictors
Supports definitions of direct and indirect range restriction, the role of sample standard deviation, and cautious correction guidance for applied validation.
- Validity
Supports framing validity as evidence for the adequacy and appropriateness of conclusions tied to a particular assessment use.
- Correlation Considerations: Range Restriction
Supports the plain-language explanation that narrowing observed variability can reduce an observed correlation and that correction requires caution.
Apply it to your work
Understand how you work before you choose what comes next.
From this guide: Carry this report-reading question into the work decision in front of you.
Build a private Work Pattern Report across ten workplace continuums, then compare the result with the demands of the role or environment in front of you.