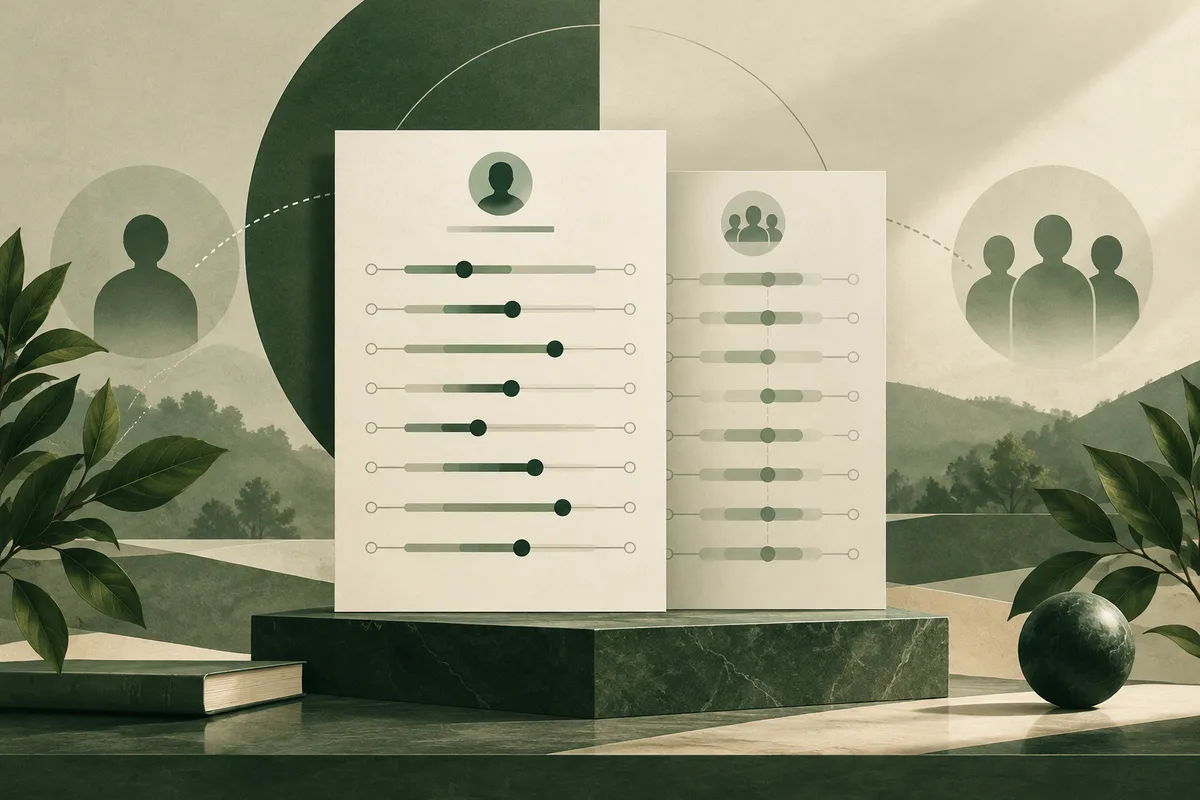
An SHL OPQ32 normative profile lets you compare a respondent’s self-reported work preferences with the reference group used for the questionnaire version and scoring method named in that report. It may also show how the respondent’s scale scores compare with one another. Those are different comparisons: a norm position describes relative standing, while a within-profile difference is descriptive unless relevant precision and interpretation evidence support more. Neither comparison alone establishes observed behavior, job fit, or performance.
What an SHL OPQ32 normative profile lets you compare
An SHL OPQ32 normative profile lets you compare your scored, self-reported work preferences with the reference group named for that report, using its stated version and scoring frame. That is an external comparison: where a score sits relative to a specified group. A chart can also show how your own scale scores are ordered against one another, but rank alone does not show that the gaps are dependable or meaningful. These are separate readings of the profile, and neither records how you behave in every situation or determines whether you will succeed in a particular role. SHL’s sample reports demonstrate why the report’s own comparison label matters: one names a Professionals 1999 group, while another names a general-population group. A reader may want the chart to identify objectively strongest traits or job fit; its narrower answer depends on exactly what the report names and defines.
Where does the report identify its comparison?
Start with the report itself, rather than the familiar product name. Find the methodology, assessment-details, or comparable panel, then read every label attached to the profile. Record the questionnaire version exactly as printed; check whether the report identifies a language or administration form; copy the norm or comparison-group name; and note how the displayed metric is defined. These details answer different questions. A version identifies which form or scoring frame the document says was used. A norm label identifies the stated comparison population. A metric definition tells you whether a plotted value is a percentile, a standardized score, a band, or something else. If one of these details is absent, mark it as unknown rather than filling the gap from memory.
The labels in SHL’s examples show why this inspection must be report-specific. The OPQ Premium Plus 2.0 International English sample report names OPQ32i and “Professionals 1999” in its methodology panel. The SHL Users Report sample dated 18 September 2018 instead identifies OPQ32r and a general-population comparison group. These examples establish that SHL report panels can state different versions and comparison groups; they do not establish which version or group appears in your document. Nor do their labels prove that either comparison group is appropriate for your language, circumstances, or the decision you are facing.
A title such as OPQ32, a familiar scale, or a chart that resembles one you have seen may make it tempting to assume the comparison is unchanged. Do not use resemblance as a substitute for the specific panel: a report can share a product-family name while naming a different version or reference group. The OPQ32n Assessment Fact Sheet identifies OPQ32n as the normative version, but that fact sheet describes that named version; it does not identify the scoring or norm used in every report carrying an OPQ32 label. Cambridge’s chapter, “The Occupational Personality Questionnaire,” provides historical context for the n, i, and r variants, while its accessible abstract does not supply the detail needed to reconstruct an individual report’s scoring. Treat those sources as context, not as a way to reverse-engineer missing fields.
If the panel does not name the norm, version, language, or metric clearly enough for your question, ask the assessor or provider to identify the exact report documentation and explain the displayed scale. You can then separate two judgments: what the document literally says its comparison is, and whether that comparison is suitable for your purpose. The first is a document-reading question; the second requires a reasoned fit between the named reference and the population or decision you care about. A legible label settles only the first. It does not, by itself, establish that the chosen norm is current or relevant to your situation.
Sources: OPQ32n Assessment Fact Sheet; The Occupational Personality Questionnaire
What does a norm position compare?
A norm-referenced position compares a person’s scored response with a reference distribution, using the metric named in that report. It describes relative standing against that group; it is not an absolute quantity of a trait or a universal rank among all workers. A percentile, when the report defines the score that way, expresses a position in relation to the norm group. A plotted point or band without an explicit metric cannot safely be translated into a percentile. Even a clearly defined percentile says nothing by itself about whether the result is desirable, how much of a preference someone possesses, or how they will behave at work.
Consider this invented example, offered only to show how labels change the comparison. A fictional report says a respondent is at the 70th percentile on one scale against a named reference group. That permits the bounded statement that the score is above the stated percentile position in that group, subject to the report’s definition and scoring. It does not mean the respondent has “70 percent” of a trait or outranks 70 percent of every working person. In another fictional chart, a point sits at position 7 on a vertical scale, but the chart does not define what 7 represents. That coordinate is not enough to call it the 70th percentile, a high preference, or an amount of behavior. It may be a transformed score or a display convention, but without a definition those possibilities remain guesses. First identify the metric; if it is not stated, the interpretation is unknown.
The group named in the report also sets the target of the comparison. In the OPQ Premium Plus 2.0 International English sample report, SHL names “Professionals 1999” in the methodology panel. That example shows a specific historical reference label; it does not establish that the group is suitable for a particular reader or that the reader’s own report uses it. A comparison against a professionals group answers a different question from a comparison against a general-population group, because the reference distributions differ. The label tells you who the report says the comparison is against, not whether the group matches your language, work context, or decision.
Relative standing can still be useful when kept within those limits. It can answer a bounded question about how a score compares with the selected reference group under the stated metric. It cannot silently become a judgment against another population, a verdict that a score is good or bad, or evidence of an absolute capacity. If the reference group or metric is missing, ask the assessor or provider to define it before drawing that comparison.
Sources: OPQ Premium Plus 2.0 International English, sample report
What does the report's version label change?
The OPQ32 name alone does not tell you whether the report’s scores are normative or ipsative, and response format alone is not a reliable shortcut. Normative scoring places a person’s score in relation to a reference group. Ipsative scoring interprets responses as relative preferences within that person’s own profile; it does not by itself locate the person against a population. The distinction matters because the two methods answer different comparison questions. A normative result needs a reference distribution to make its external comparison; an ipsative profile instead describes the respondent’s pattern among their own responses. A reader cannot assume that every chart under the OPQ32 family name supports the same between-person comparison, nor infer the scoring method solely because items used a particular response format.
SHL’s OPQ32n Assessment Fact Sheet explicitly calls OPQ32n the normative version and describes its five-point rating format. This supports a claim about that named version, not every report whose title includes OPQ32. The fact sheet’s label helps readers understand that version’s stated scoring orientation, but it does not give a universal rule for interpreting any unlabeled chart or establish every transformation used in an individual report. The actual report’s version, method, norm label, and metric remain the relevant record for the result being read.
The accessible abstract of Cambridge’s chapter “The Occupational Personality Questionnaire” supplies historical context for the n, i, and r variants and their differing response and scoring approaches. The full chapter is not openly available in the source record, so its abstract cannot support a detailed reconstruction of each scoring procedure. In combination with SHL’s version-specific fact sheet and report examples, it supports the narrower conclusion that the family name covers distinctions a reader should not collapse. It does not show that every historical variant is still offered or that versions are interchangeable today.
This is why “forced-choice means ipsative” is an unsafe inference: the response format does not, on its own, establish the score comparison the report presents. Likewise, seeing “OPQ32” is insufficient to infer that a score is normative, identify its norm group, or determine whether two scale scores can be compared across people. Those questions depend on the exact version and scoring documentation. If the report omits those details, ask the assessor or provider which version and scoring method generated it and what comparisons the displayed scores support. Do not try to reverse-engineer the method from the questionnaire’s appearance.
Version history is useful for explaining why labels matter, but it cannot settle the status or interpretation of a contemporary report. Current interpretation should follow the exact report and current provider documentation. When those sources do not specify whether a comparison is normative or ipsative, preserve that uncertainty: the report’s name or item format has not supplied the missing evidence.
Sources: OPQ32n Assessment Fact Sheet; The Occupational Personality Questionnaire
When is a visible profile gap dependable enough to interpret?
A plotted gap is dependable enough to interpret only when the report’s scoring documentation supports that level of precision and the proposed interpretation fits the scale. The picture establishes an ordering on the displayed metric: one point appears higher. It does not, by itself, establish how precisely either score was measured, whether their difference would persist on another administration, or whether the difference matters in behavior. Those are separate claims and require separate support.
ETS’s “Test Reliability—Basic Concepts” explains reliability as a question about the consistency or precision of scores, with measurement error expressing uncertainty around an observed result. This is a general measurement distinction, not an OPQ32 finding. A reliability estimate, where available, addresses how much confidence to place in a score under specified conditions; it does not tell a reader what a scale means, whether the instrument measures the intended construct, or whether a particular gap has practical importance. Those latter conclusions depend on the instrument, its intended interpretation, and the decision being considered. The ETS guidance supplies no OPQ32-specific reliability coefficient, standard error, confidence interval, or threshold for comparing two profile points. Precision information also has to match the score being interpreted: a general statement about an assessment, or an estimate from a different version or population, may not answer how much confidence to place in these particular plotted values. The relevant question is not simply whether the instrument has a reliability statistic, but whether its technical evidence applies to this score, administration, and proposed comparison. Even evidence that a difference is measured consistently would still leave its substantive meaning to be established.
Imagine an invented report in which the point for Scale A is visibly above the point for Scale B. The reader can accurately say that A is plotted higher than B on this chart. Without version-specific technical evidence about the precision of these scores and the interpretation of differences on these scales, the reader cannot conclude that the gap is stable, important, or a meaningful behavioral contrast. The visual distance may be easy to notice while its measurement uncertainty remains unknown. A chart’s spacing, line, or apparent separation does not supply the missing precision evidence.
Do not create a cutoff by deciding that a certain number of chart units must count as a meaningful difference. Ask the assessor or provider for the technical documentation applicable to the exact version and report: how the displayed scores were derived, what precision information is available, and whether the manual supports comparisons between these scales. If the documentation does not provide a defensible interpretation of the gap, leave its magnitude uninterpreted. The points can still prompt a useful reflection question—such as whether the two tendencies feel different in a particular setting—but that question is a starting point for inquiry, not proof that the plotted contrast is dependable or consequential.
Sources: Test Reliability—Basic Concepts
Why does the norm population matter?
The norm population matters because a norm comparison is defined against people represented in a reference group, while evidence that scores vary across countries describes groups in aggregate. The two facts are related, but they answer different questions. A cross-country finding can show that population context belongs in careful interpretation; it cannot reveal why one person received a particular score or determine which comparison group should have been selected for that person.
The publisher abstract for “A cross-validation of between country differences in personality using the OPQ32” reports two historical datasets: more than one million OPQ32i cases from 31 countries and more than 110,000 OPQ32r cases from 39 countries. The researchers used multilevel analyses and cross-validation against external country indicators. The abstract reports that country-level effects accounted for 3%–15% of total scale-score variance across the analyses. This is a range across scales or analyses, not a single universal percentage, and the abstract does not provide a basis here for assigning a specific value to an individual scale or report. Its result concerns the distribution of scores in those historical datasets and formats. In this context, the reported percentage describes a component of score variance associated with country grouping in the analyses; it is not the proportion of a person’s score caused by nationality. Cross-validation against external indicators adds a check on whether country-level patterns aligned with those indicators in the study’s data. It does not turn the association into an explanation of mechanism, and it does not evaluate the suitability of every norm used in later reports.
That finding makes a population label consequential to the question a norm answers: the comparison refers to a particular reference population, and country-level variation was present in the studied data. But the result does not identify the cause of that variation. The analysis, as summarized in the abstract, does not isolate whether country differences reflect language, occupational composition, sampling, response practices, cultural influences, or another factor. Nor does aggregate variance show that a particular person’s score is inaccurate, that their report used a mismatched norm, or that a country-specific norm would improve a given decision. Group variation and individual norm misfit are distinct claims; the first does not establish the second.
Consider a practical, hypothetical case: two otherwise similar reports name different reference groups, one a broad international group and one a group defined for a particular country. Their norm-referenced positions answer comparisons to the populations each report names. The cross-country study gives a reason to notice and ask about those labels, but it cannot tell this reader which group is appropriate. That requires information about the report’s actual norm, the population and purpose it was designed for, and the decision at hand. The hypothetical illustrates a question to ask; it is not a result reported by the study.
Accordingly, ask the assessor or provider to identify the target population represented by the norm and explain why that reference group fits the intended use. A clearly named norm makes the comparison visible; it does not automatically make the norm suitable. The historical group-level result supports attention to population context, while leaving the individual interpretation open until the report’s own reference and purpose are known.
Sources: A cross-validation of between country differences in personality using the OPQ32
What can one OPQ32 equivalence study establish?
One OPQ32 study offers evidence against the absolute claim that cross-group comparison is always impossible, but it does not certify every comparison. “Construct equivalence of the OPQ32n for Black and White people in South Africa” examined responses from 248 Black and 476 White South African participants using the OPQ32n. Its question was whether the instrument’s measured construct structure showed sufficient similarity in those two defined groups. The sample, version, country, and group definitions are part of the finding: the result belongs to that setting, rather than to every OPQ32 report or every population a reader might encounter.
The authors used multigroup covariance-structure analyses, comparing the fit of models that imposed increasingly similar structures across the groups. In practical terms, structural equivalence asks whether the pattern of relationships among the scales can reasonably be treated as similar in the groups examined. The reported fit picture was mixed rather than a single all-clear: several fit indices supported substantial similarity in correlation structures, while comparisons involving covariance structures were less conclusive. That combination matters. The favorable indices are evidence and should not be discarded; the uneven results also make a blanket certification too strong. The paper’s own conclusion is cautious about what structural findings establish.
This distinction limits the meaning of “equivalent.” Similar relationships among scales do not show that the groups have the same average scores, that a given score has precisely the same meaning for each person, or that every questionnaire item functions identically. Nor does structural similarity establish that score differences are equally precise, that a cutoff is fair, or that a hiring or performance decision based on the result is justified. Those are further claims requiring evidence suited to the score comparison, item behavior, and actual decision. The study tests a structural question; it does not answer all these other questions by implication.
The useful conclusion sits between two categorical positions. It is inaccurate to say this evidence makes any comparison across groups impossible: the South African OPQ32n analyses found meaningful structural similarity in the specific groups tested. It is equally inaccurate to say the paper proves full interchangeability across groups or uses: the covariance results were not uniformly strong, and the study’s scope is bounded. A reader considering another version, population, language, score-level contrast, or consequential use needs evidence that addresses that case. This study makes a narrow comparison more plausible under its tested conditions; it cannot substitute for the missing evidence elsewhere.
The distinction between correlation and covariance structures also helps explain why the paper’s conclusion is deliberately qualified. A correlation pattern concerns how scales vary in relation to one another; covariance comparisons additionally retain information about their variances and shared scale of variation. Similarity on one structural view therefore need not mean that every numerical property of the scores aligns. The article reports fit evidence across these model comparisons, but its abstract or headline cannot be reduced to a universal pass/fail certificate. A reader should preserve both parts of the result: there is supportive evidence for structural similarity, and the less decisive covariance picture narrows the claim. Neither part licenses an assumption about another group or a different level of equivalence.
Sources: A cross-validation of between country differences in personality using the OPQ32
What extra evidence is needed before connecting a profile to work?
A work-related profile narrative is an interpretation of a person’s self-reported preferences; it is not a direct observation of what that person did on a particular task. To move from narrative to behavior, ask what concrete actions would count as an example, in which setting, and what other explanation might fit. Work behavior depends on the task, constraints, relationships, resources, and moment. A preference may be expressed differently when the person has discretion than when a process tightly limits their options. Treating the narrative as a settled description of conduct skips those contextual steps.
SHL describes the OPQ32 as an occupational personality questionnaire and presents it for organizational assessment and development contexts in “Occupational Personality Questionnaire (OPQ32) for Managers, Experts and Graduates.” That product framing gives a fair reason to consider the instrument in work-related reflection or a broader assessment process. It does not, by itself, demonstrate that a particular profile predicts an individual’s performance or fit for a particular job. The inferential step from preference to observed conduct, and from conduct to a target outcome, needs support that matches the intended use. This is a boundary on what the provider page establishes, not a claim that occupational questionnaires can never contribute useful evidence.
For a low-stakes reflection, imagine a report narrative that suggests someone prefers to consider options before committing. Use it to pose a question, not to label the person: recall a specific work episode in which they took time to compare alternatives, then look for a counterexample in which they decided quickly. Note what differed between the situations—urgency, available information, responsibility, or the cost of delay—and whether another explanation accounts for the contrast. These episodes can reveal what to investigate next or help a coaching conversation become more specific. They are illustrative prompts, not observations from the OPQ study or proof that the profile is accurate.
If the conclusion will affect hiring, promotion, assignment, or another consequential decision, personal recollection alone is not enough. Seek independent evidence tied to the actual work requirement, gathered in a way appropriate to that decision, and consider the other information and safeguards in the process. An OPQ result may contribute to a broader supported process when the exact intended use and evidence fit; it should not operate as a standalone rule or a substitute for evidence of task-relevant behavior. Conversely, occupational context does not make every use valid automatically. The question is whether the evidence supports this interpretation for this purpose, not whether a profile sounds plausible.
This method is useful precisely because it separates a report’s suggested theme from a claim about a person. The same preference description could lead to different actions under different constraints, and one episode cannot establish a stable pattern by itself. Looking for a counterexample prevents a single memorable event from becoming confirmation; naming context helps identify which features of the situation may have shaped the action. If the question is practical—such as whether a role requires rapid independent decisions—the next evidence should concern that requirement directly. The reflection can help formulate the question, while evidence collected against the work demand must carry any consequential conclusion.
Sources: Construct equivalence of the OPQ32n for Black and White people in South Africa
What should you do next with an unclear or consequential result?
If a report leaves out a detail needed to interpret its comparison, ask the assessor or provider for that detail before deciding what the result means. Request the exact OPQ32 version, the norm group used, and the metric shown for the score in question. These are three specific fields, not a request for a general reassurance that the report is reliable. A report may be worth clarifying rather than discarding: the answer could establish what its profile compares. Until it does, keep any conclusion that could affect a consequential decision provisional.
If you are using the profile for private reflection, choose one work-related interpretation and test it against a real episode. For example, recall one occasion when you delayed a decision to compare options, then a counterexample when you decided quickly. Note what differed in the task or circumstances; do not treat either memory as proof of a stable trait or as a job recommendation. If you want a broader prompt for examining how you decide and collaborate, the optional [Work Pattern Report](/assessment) offers a separate low-stakes reflection. It has no norm, cutoff, type, or job recommendation, so it cannot clarify or validate an OPQ32 score. Use it only to generate observations for your own reflection.
Sources: Work Pattern Report
Questions readers ask
What does an SHL OPQ32 normative profile compare?
It compares a respondent’s self-reported work preferences with the reference group used for the version and scoring method named in the report.
Is an OPQ32 profile position a percentile?
Only if the report identifies the displayed metric as a percentile. A chart position or numbered scale does not establish that by itself.
Can differences between OPQ32 profile scales show which preference is stronger?
They show relative positions on the displayed metric. Whether a gap is dependable or meaningful requires relevant precision information and an appropriate interpretation method.
Does an OPQ32 normative profile establish job fit or performance?
No. It describes self-reported preferences relative to a specified reference. A work conclusion requires separate evidence suited to the behavior, role, and intended decision.
Sources and notes
- OPQ32n Assessment Fact Sheet
SHL labels OPQ32n the normative version, specifies its five-point rating format, and differentiates its stated development/research positioning from OPQ32r for selection/high-stakes purposes.
- The Occupational Personality Questionnaire
The chapter provides historical context for OPQ32n, OPQ32i, and OPQ32r and their differing response/scoring approaches.
- OPQ Premium Plus 2.0 International English, sample report
This sample report's methodology panel names OPQ32i and a Professionals 1999 comparison group, demonstrating that version and norm labels are report-specific.
- OPQ Users Report, sample report dated 18 September 2018
The sample names an OPQ32r version and general-population comparison group, frames the profile as self-reported work preferences, and illustrates narrative interpretation.
- Test Reliability—Basic Concepts
ETS explains that reliability concerns score consistency/precision and measurement error, a distinct question from what a score means or whether it supports a use.
- A cross-validation of between country differences in personality using the OPQ32
The publisher abstract describes historical OPQ32i data from over one million cases in 31 countries and OPQ32r data from over 110,000 cases in 39 countries; multilevel analyses attributed 3%–15% of total scale-score variance to between-country effects.
- Construct equivalence of the OPQ32n for Black and White people in South Africa
The study used OPQ32n data from Black (n=248) and White (n=476) South African groups and multigroup covariance-structure analyses to test structural equivalence; its reported fit indices supported substantial similarity in correlation structures but were less conclusive for covariance comparisons, and the authors caution against treating structural results as full scale equivalence.
- Occupational Personality Questionnaire (OPQ32) for Managers, Experts and Graduates
SHL describes OPQ32 as an occupational preference questionnaire and lists organizational assessment/development contexts; its broad product description does not establish that a norm position predicts an individual's job performance.
- Work Pattern Report
The approved publication product is a 100-item reflection report across ten decision-and-collaboration continuums; its result has no norm, cutoff, type, or hiring/job recommendation.
Apply it to your work
Turn a work-style question into specific observations
From this guide: Use a low-stakes reflection prompt if you want to examine how your decision and collaboration patterns show up in work examples.
An OPQ32 norm position describes reported preferences relative to its specified reference; it does not establish how those preferences appear in your work. If you are considering a work decision, first identify the behavior you want to understand and compare the interpretation with concrete examples. The Work Pattern Report offers a separate, low-stakes way to reflect on decision and collaboration patterns. It does not provide a norm, hiring score, or job recommendation.