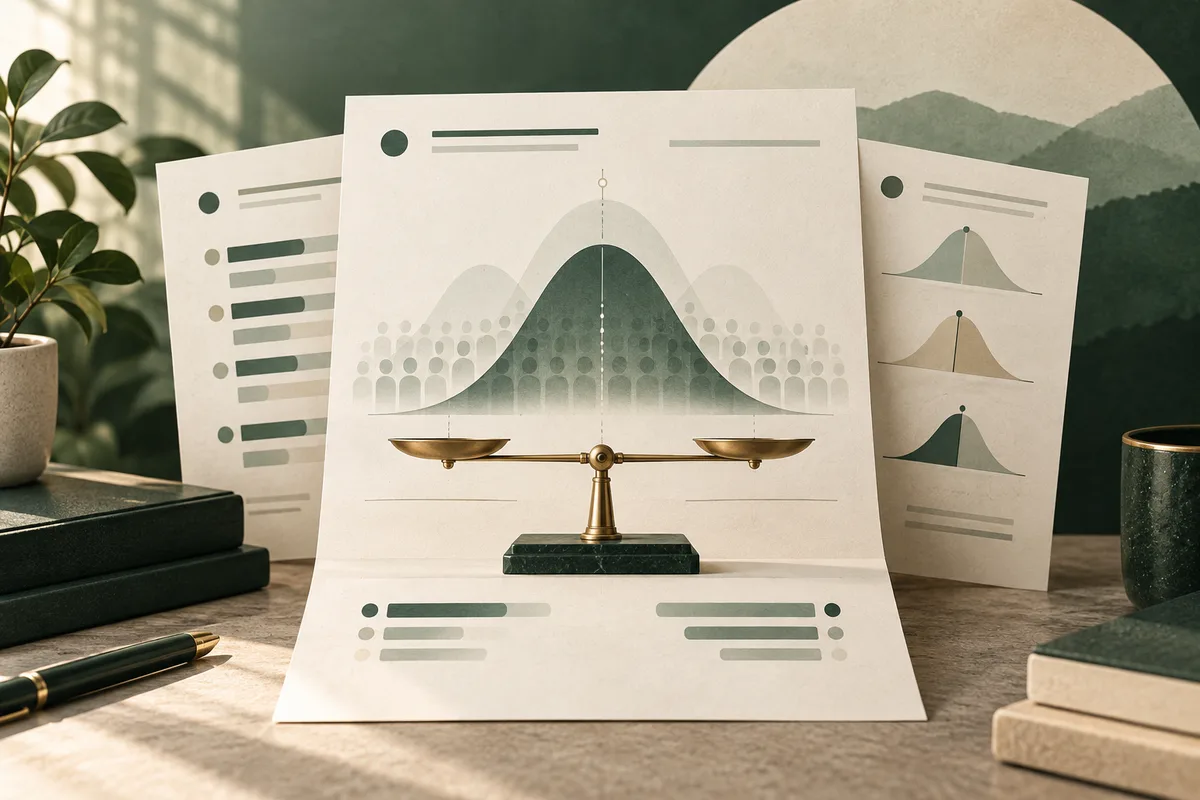
A personality report’s reference distribution shows the position of your observed score among the scores of a defined comparison group. It is the background that makes a raw score interpretable: the same number can look different when compared with different groups, test versions, or scoring systems. A reference distribution can therefore help you understand relative standing, such as whether your score is near the middle or toward one end of that group. It cannot, by itself, establish that you have a fixed identity, explain every behavior, predict a particular outcome, or prove that one score is better than another. Read the group, scale, date, and uncertainty before acting on the result.
The distribution is a comparison frame, not a verdict
Imagine a report gives you a raw score on a broad personality scale. A raw score is the direct total produced by the scoring rules, such as a sum or average of item responses. On its own, that number has limited meaning. The reference distribution supplies the comparison frame: it shows how scores were spread among the people used as the reference group.
If your score is described as being around the middle of that distribution, the modest conclusion is that it is near the middle relative to that group. If it is toward one end, the report may describe your measured tendency as relatively lower or higher than many people in that group. The word relatively matters. The result is about position on a measured scale, not a moral grade or a complete description of you.
This is why two plausible readings can both sound tempting but only one is justified. “My score is high, so I am naturally this way in every setting” turns a relative result into a global identity claim. “My responses placed me toward this end of this scale compared with this group” stays close to what the distribution actually supports. The second reading gives you something observable to check without treating the report as a verdict.
What a reference distribution contains
A reference distribution is more than a single average. It may include the range of observed scores, the center of the scores, their spread, and the conversions used to report them. The center is often summarized by a mean or median. The spread indicates how close together or far apart scores are. A report may then convert your raw score into a standard score, a band, or a percentile rank.
A percentile rank expresses your relative position in a defined group. In the conventional explanation used by testing organizations, a score at the 84th percentile is higher than the scores of about 84 percent of that group, subject to the report’s handling of tied scores. It does not mean that you answered 84 percent of items correctly, nor that you possess 84 percent of a personality trait.
The distribution also has an important boundary: it describes the group from which the reference information was obtained, or the population that sample is intended to represent. A report that says “general population” without describing the population, sample, dates, language, or other relevant details leaves you with less context than a transparent report would provide.
A worked comparison: the same score, two meanings
Consider an unnamed report that converts a raw score into a percentile. The report places the score at the 62nd percentile in one reference distribution. That means the score is above the scores of roughly 62 percent of that defined group. It does not mean that the person is 62 percent outgoing, careful, agreeable, or any other trait label. The meaning depends first on what the scale measures and how the publisher defines it.
Now keep the raw score and the instrument constant, but compare it with a different distribution. The percentile could change because the comparison group has a different score pattern. A group selected from one occupation, one organization, one age range, or one country may not have the same distribution as a broader population. The raw response pattern did not change. The reference frame did.
This comparison is useful when a report seems to conflict with another report. Before deciding that one result is wrong, check whether the instruments measure the same construct, use comparable scales, and rely on similar reference groups. Similar-looking numbers do not become interchangeable simply because both are called scores.
Ask who is represented before interpreting your position
The most important question about a distribution is often not “Where am I?” but “Compared with whom?” A norm group is the group whose score distribution gives individual scores their relative meaning. The useful details include the group’s intended population, how participants were recruited, when the data were collected, and whether the sample resembles the people for whom the report is being used.
A distribution based on people who volunteered for an online questionnaire may answer a different comparison question from a carefully sampled population. Neither label automatically makes the result useless. It does mean that the report should state what comparison is being offered. A group of current employees may be reasonable for describing that organization’s participants, but it may be a poor basis for general claims about everyone who might take the assessment.
Age, language, education, culture, disability status, and other features can affect how a test is understood and how responses are produced. APA guidance says that the reliability and validity of instruments developed for a specific population should not simply be assumed to transfer to other groups without relevant adaptation and evidence. Treat a mismatch as a reason for caution and context, not as a judgment about the person taking the test.
A percentile is not a percentage or a probability
Three expressions are easy to confuse. A percentage usually describes a proportion, such as the share of items answered in a particular way. A percentile rank describes relative standing among a defined group. A probability describes how likely an event is under specified conditions. A personality report’s percentile is normally the second of these, not the first or third.
Suppose a report places a score at the 25th percentile on a scale measuring a tendency. The defensible translation is that the score is lower than most scores in that reference group, or that most of the group scored above it, depending on the exact convention. It is not evidence that a person will show the tendency one quarter of the time. Nor does it estimate the chance of succeeding or failing at a job, relationship, or life decision.
The scale label still matters. A lower relative score can be useful or inconvenient depending on the setting and the behavior being considered. Even then, the report needs evidence connecting the score to that outcome before making a prediction. A distribution supplies comparison information. It does not supply an outcome criterion by itself.
Where uncertainty enters the picture
The score you see is an observed score from a particular administration. It can be affected by the particular items included, response conditions, interpretation of wording, attention, and other sources of measurement error. Measurement error is not a statement that the whole assessment is worthless. It is a reminder that a reported value should not be treated as infinitely exact.
Uncertainty can also belong to the distribution itself. When norms are estimated from a sample rather than every member of a population, the sample may not describe the wider population perfectly. A small difference in percentile or band may therefore be less meaningful than the report’s neat formatting suggests. The relevant question is whether the result would support the same broad interpretation if reasonable error were considered.
This matters most near a boundary. If a report divides scores into low, average, and high bands, a score close to a boundary should not be read as a sharp change in personality. The Standards for Educational and Psychological Testing note that precision depends on the interpretation and that people close to cut scores can be more vulnerable to misclassification. A band is a communication choice, not proof of a natural dividing line.
What the distribution cannot tell you
A reference distribution cannot tell you whether a trait is good or bad. It cannot tell you why you received the score, whether the score will remain identical, or how you will behave under every set of circumstances. It also cannot turn a general personality assessment into a clinical diagnosis. Those are different claims requiring different constructs, methods, and evidence.
It cannot tell you that someone in a higher percentile will always communicate better, lead more effectively, or fit a role more closely. A score may contribute information to a carefully defined decision only when evidence supports that use, the scale is appropriate, and other relevant information is considered. The International Test Commission advises against overgeneralizing results to characteristics the test did not measure and against using a single score as the whole basis for a decision.
This limit is not a technical footnote. It protects the person reading the report from turning a comparison into a stereotype. It also protects a coach, manager, or reader from making a consequential decision with more confidence than the evidence allows.
Turn a relative result into an observable question
The most useful next step is to translate the report into a question about behavior in context. If the report places you relatively high on a tendency related to planning, ask: “When a task is open-ended, do I usually create a sequence of steps before starting?” If the report places you relatively low, ask: “In which settings do I prefer flexibility, and when does that create a practical cost?” These questions test the interpretation against observations rather than treating the label as a conclusion.
Look for more than one recent example and for exceptions. A tendency may appear in one setting and be constrained in another by time pressure, role expectations, health, culture, or the needs of other people. The goal is not to prove the report right. It is to find out whether the interpretation helps you notice a repeatable pattern and choose a proportionate action.
For a self-reflection or coaching use, a small experiment may be enough: record the situation, the behavior, the immediate result, and what you would try next time. For work selection or other high-stakes uses, personal reflection is not a substitute for documented validity evidence, fair procedures, and multiple sources of information.
A practical checklist for reading the page
Before you accept the report’s interpretation, find these details. First, identify the construct and scale: what tendency is measured, and what do the items actually cover? Second, identify the score type: raw score, standardized score, percentile rank, band, or facet result. Third, identify the reference group and ask whether it fits the intended use.
Then check the date and source of the norms. Norms may become less useful when the population or context changes, and the testing standards call for periodic review where continued utility is in question. Look for information about sample size, recruitment, weighting, language, and relevant subgroup evidence. Do not fill missing details with assumptions.
Finally, look for precision, reliability, validity, and use guidance. Reliability concerns the consistency or precision of scores under specified conditions; it is not the same as validity, which concerns whether an interpretation or use is supported. Ask what evidence supports this particular conclusion, for this population, and for this purpose. If the page offers only a percentile and a confident life summary, the reference distribution is doing more work than it can safely do.
Questions readers ask
Does a higher percentile mean I have more of a personality trait?
It means your score is higher relative to the defined reference group on that scale. It does not mean you have a particular percentage of the trait, show it all the time, or are better than people with lower scores. The scale definition and intended use still determine what the result can mean.
Why can my percentile change when my raw score stays the same?
A percentile depends on the comparison distribution. If the report uses a different reference group, age range, language version, or norm set, the same raw score can occupy a different relative position. Check the report’s norm group and scoring documentation before comparing results.
What should I do if my score is close to a band boundary?
Treat the boundary as a broad communication aid, not a sharp psychological line. Check the report’s precision information, consider whether the comparison group fits, and examine several observable examples in context. Avoid making an important decision from that score alone.
Sources and notes
- APA Dictionary of Psychology: Norm-Referenced Test and Test Norm
Supports the definitions of norm-referenced interpretation and test norms as comparisons with a specified group.
- E. T. S. Standards for Quality and Fairness 2014
Supports the definitions of norm group, norms, percentile rank, observed score, and measurement error.
- The Standards for Educational and Psychological Testing
Supports distinctions between norm and criterion interpretations, appropriate reference groups, norm precision, updating norms, and cut-score uncertainty.
- APA Guidelines for Psychological Assessment and Evaluation
Supports considering the normative population, cultural and language context, and limits on transferring evidence across groups.
- International Guidelines for Test Use
Supports responsible interpretation using appropriate norms, measurement error, validity evidence, context, and multiple information sources.
Apply it to your work
Understand how you work before you choose what comes next.
From this guide: Carry this report-reading question into the work decision in front of you.
Build a private Work Pattern Report across ten workplace continuums, then compare the result with the demands of the role or environment in front of you.