A transparent personality report should let a careful reader follow the main route from response to conclusion. It should identify what each scale measures, explain item scoring and any reverse-keyed items, state how missing answers are handled, show how scale totals are transformed, identify the norm group behind percentiles or bands, and report uncertainty. It should also separate the scoring rule from the interpretation rule: adding or weighting answers is one operation, while saying what the resulting score means is another. Finally, it should name the assessment's intended use and the evidence supporting that use. A polished explanation is not enough if the report hides its inputs, comparisons, cutoffs, error, or limitations.
Start with the path your answers take
Imagine opening a report that says, “Your score is high, so you are highly dependable.” The missing information is not a minor technical footnote. You need to know which answers contributed to the score, whether some answers counted in the opposite direction, whether every item was required, and why “high” leads to that description.
A useful report gives this path in plain language. For example: responses to a defined group of items are coded, reverse-keyed items are recoded where appropriate, the item values are summed or averaged into a scale score, that score is transformed or compared with a stated reference group, and an interpretation is attached to the resulting range. The exact formula may be proprietary, but the stages and the information needed to understand them should not be mysterious.
This is a reader's standard for inspectability, not a demand to publish source code. If a provider cannot explain the route at all, you cannot tell whether the report is describing a measured tendency, applying an arbitrary label, or making a prediction that was never validated.
Define the construct and scoring rules
The report should say what the scale is intended to represent and what it does not represent. A scale labelled “dependability,” for instance, might refer to a particular trait definition, a set of work habits, or a provider's own composite. Those are not interchangeable. Readers should not have to infer the construct from a flattering paragraph written after the score was calculated.
The explanation should describe the item content or facets at a useful level, the response format, the direction of the scale, and the population for whom the interpretation was developed. If a score is self-reported, the report should say that it reflects the person's answers about their usual tendencies in that setting. It is not direct observation, a life history, or a diagnosis.
The Standards for Educational and Psychological Testing treat validity as evidence for an interpretation and use, not as a permanent property that makes every future claim true. That distinction keeps a report's wording proportionate: evidence that supports a trait description does not automatically support a hiring prediction or a clinical conclusion.
A transparent report should disclose the decisions that can materially alter a result. At minimum, that usually includes how response options are coded, which items are reverse-keyed, whether a scale is a sum or an average, whether items have different weights, and how unanswered items are treated. “The algorithm scored your responses” is not an explanation of any of these choices.
Missing answers deserve special care. A provider might require completion, calculate a score only when enough items are answered, or use another documented rule. Each choice changes who receives a score and how comparable scores are. The report should identify the rule used for this assessment and flag when too much information is missing for a stable interpretation.
The Standards say that the basis and rationale for composites should be given, including how components are combined, transformed, standardized, or weighted. For a reader, that means a short worked diagram or formula is often more useful than a long technical appendix. If a scale is a simple average, say so. If it uses differential weights or an unreported adjustment, explain why and where it enters the calculation.
Separate the score from its comparison group
A raw score is a result on the instrument's own scoring scale. A percentile rank is a position relative to a specified comparison group. A band such as “lower,” “typical,” or “higher” is a category created by a rule. A transparent report labels these layers instead of presenting them as one natural fact about the person.
The report should identify the norm group, the date or edition of the norms when relevant, and whether the comparison is appropriate for the reader's context. It should state whether the reference group is a general sample, an occupational sample, or another defined population. Without that information, “higher than average” has no stable meaning. A percentile is also not a percentage of the trait and does not say that a person performed correctly that proportion of the time.
If the report uses cut points, it should show how they were chosen and what decision they are meant to support. Convenient categories can make a continuous score look more decisive than it is. A small difference around a boundary may reflect rounding or measurement uncertainty rather than a meaningful change in the underlying tendency.
Make uncertainty visible at the point of use
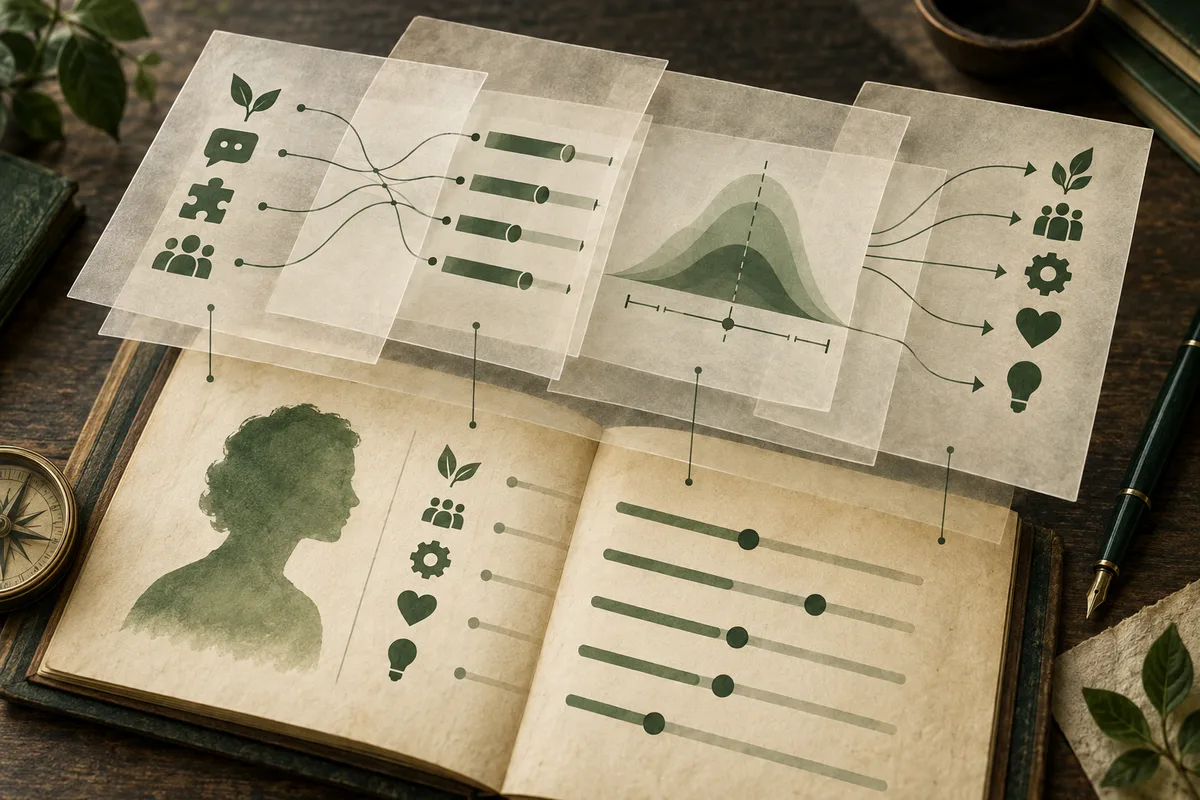
Every score contains some measurement error. Reliability asks how consistently a score behaves under specified conditions; it does not by itself prove that the scale measures the intended construct. A transparent report should therefore provide a suitable precision estimate, such as a standard error of measurement or an interval, and explain how to read it.
The interval should appear beside the interpretation it qualifies, not be buried in a methods page. If the report places a result in a band, show whether the plausible range crosses a neighbouring band. If two facet scores differ slightly, do not call the difference meaningful without evidence that the difference is reliable and interpretable. The testing standards warn against overinterpreting information subject to considerable error and ask score reports to guide the confidence warranted by an interpretation.
A good sentence might say that the observed score is an estimate and that nearby values remain plausible. That is not evasive. It tells the reader when the report can support a broad reflection, and when it cannot support a sharp ranking or consequential decision.
Connect each interpretation to evidence
The report should map claims to evidence. If it says a scale describes a tendency, it should point to evidence about the construct and the instrument's internal structure. If it says scores relate to an outcome, it should identify the outcome, the population studied, the size and uncertainty of the association, and the conditions under which the finding applies. A reliability coefficient alone cannot carry that argument.
The intended use must be explicit. A report designed for self-reflection may help a reader generate questions about recurring situations. That does not make it a selection tool, and neither use makes it a clinical assessment. The Standards place responsibility on users to evaluate evidence in the particular setting and require a rationale when scores are used for a purpose with little or no supporting validity evidence.
Readers should be wary of interpretations that leap from a score to destiny: “will succeed,” “is a bad teammate,” or “has a disorder.” A transparent report uses conditional language and observable examples. It tells the reader what the score may help them consider, rather than treating a statistical summary as a verdict.
Explain automated steps and human choices
Some reports use a fixed scoring formula. Others add automated text analysis, adaptive item selection, or a model that combines several inputs. The report should identify every input that affects the result, the stage at which it is used, and whether a human reviews or changes the output. “Automated” does not mean neutral, and “proprietary” does not excuse a provider from explaining the relevant behavior of the system.
This matters especially when a report is used in employment. The U.S. Equal Employment Opportunity Commission has warned that automated tools can disadvantage people with disabilities and that opacity can make it harder to understand what is being measured, seek an accommodation, or detect discrimination. A responsible report or assessment notice should identify the purpose, provide an accessible route for questions and accommodations, and avoid hidden signals such as facial, voice, speed, or interaction features unless their relevance and evidence are clear.
For personal reflection, the same principle is simpler: disclose whether the result came only from questionnaire answers or also from other data. Readers can then decide whether the interpretation matches the information they knowingly supplied.
Use a disclosure that a reader can test
A compact scoring disclosure should answer six questions. What is measured? Which responses enter each scale? How are they coded, reversed, combined, and transformed? How are missing answers handled? Which norms, bands, or cutoffs turn the number into a comparison? What uncertainty and intended-use limits apply? A reader should be able to use the disclosure to ask a specific follow-up question, not merely admire its technical vocabulary.
One practical test is to ask whether another careful reader could reproduce the same broad result from the same responses and the published rules. They may not reproduce a rounded display value if the provider withholds a precision setting, but they should understand why the result falls in its stated range. A second test is counterfactual: if one answer changed, does the report explain whether and why the scale or interpretation would change?
The International Test Commission and Association of Test Publishers describe digital assessment quality as covering design, delivery, scoring, analysis, interpretation, and reporting. That whole process is the right frame. Transparency is not just revealing a formula after the assessment; it is documenting the controls that keep the result accurate enough and fair enough for its proposed use.
Turn the report into a bounded decision
Before acting on a report, write down the decision it is meant to inform. For self-reflection, the next step might be to compare the interpretation with several recent situations and record what fits, what does not, and what context changed the behavior. For coaching, use the score as one prompt among conversation, goals, and observed actions. For work decisions, ask for documented job relevance, validation evidence for that use, accessibility, and a meaningful human review process.
Then check the report itself: identify the construct, follow the scoring path, locate the norm group, read the uncertainty statement, and mark claims that go beyond the evidence. Do not retake the assessment simply to obtain a preferred label or coach yourself into answers. If the result conflicts with experience, treat the conflict as information about the instrument, the context, or the interpretation, not as proof that either the person or the report is defective.
The bottom line is modest but useful. A transparent algorithm makes the report inspectable. It does not make every interpretation true. Use the live topics library for further guidance on scores, norms, reliability, validity, and responsible report use, then make only the decision that the disclosed evidence can support.
Questions readers ask
Does a transparent personality report have to publish its source code?
No. It should explain the inputs, scoring stages, transformations, missing-data rules, comparisons, uncertainty, and intended use clearly enough for readers and qualified reviewers to understand how conclusions arise. Publishing source code can help in some settings, but code alone would not show whether the construct, norms, or interpretation is valid.
Why is a scoring formula not enough to prove a personality report is accurate?
A formula describes how responses become a score. Accuracy also depends on what the items measure, how consistently they do so, whether the norms fit the reader, and whether evidence supports the report's intended interpretation. Reliability concerns consistency, while validity concerns the meaning and use of scores.
What should I do if a report hides its scoring rules?
Ask the provider how items are combined, how missing answers are handled, which comparison group is used, how uncertainty is reported, and what uses have evidence behind them. If those answers are unavailable, treat the report as a prompt for reflection at most, and avoid using it for clinical, hiring, or other high-consequence decisions.
Sources and notes
- Standards for Educational and Psychological Testing
Supports disclosure of composite-score rationale, weighting, transformations, confidence guidance, validity evidence, and limits on interpretation.
- ITC/ATP Guidelines for Technology-Based Assessment
Supports treating digital assessment design, delivery, scoring, analysis, interpretation, reporting, fairness, accessibility, and privacy as connected quality questions.
- U.S. EEOC and DOJ Warn against Disability Discrimination
Supports the need for safeguards and accommodation processes when algorithmic tools are used in employment decisions.
- Testimony of ReNika Moore on Automated Decision-Making Systems
Supports concerns about opaque measurement standards, proxy variables, job relevance, disability access, and difficulty detecting discrimination.
Apply it to your work
Understand how you work before you choose what comes next.
From this guide: Carry this report-reading question into the work decision in front of you.
Build a private Work Pattern Report across ten workplace continuums, then compare the result with the demands of the role or environment in front of you.