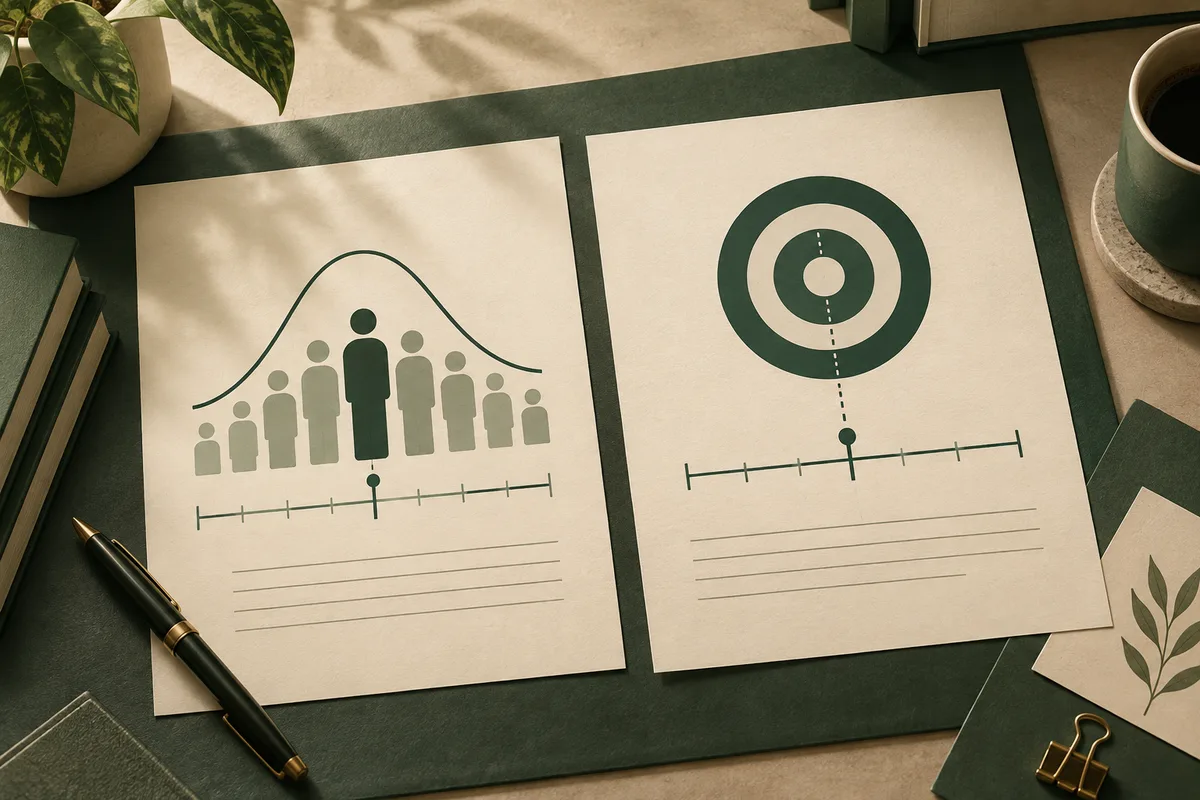
Classify the report statement, not the whole report: a comparison with a specified population’s score distribution is norm-referenced; a comparison with a defined domain or rule is criterion-referenced. A report can use both for one score. If it names neither, the comparison is unresolved: ask for documentation tied to that report version and avoid conclusions that depend on it.
What question is the report’s sentence answering?
To classify a personality report, select the exact sentence making a claim and ask what its score is compared with. If the sentence relates the score to a specified group’s distribution, it is norm-referenced. If it relates the score to a defined domain or criterion, it is criterion-referenced. The NCME Assessment Glossary distinguishes these interpretations by their reference point: a population distribution in the first case, a criterion domain in the second. The wording around a score, rather than the report’s title or overall format, is the object to examine.
For example, a report could display a score beside a comparison group and elsewhere state that a response pattern meets a named behavior standard. Those statements would answer different questions even if they draw on the same assessment. A population comparison describes where a score sits relative to that group; a criterion comparison describes its relation to a stated domain or rule. Calling the whole document “norm-referenced” or “criterion-referenced” can conceal that difference. First identify which sentence supplies the interpretation, then follow the reference named in that sentence or its documentation.
Keep the score description separate from the reference relation. “A score of 24 on Scale X” tells you the reported value and scale, assuming the scoring method is documented; it does not by itself say how to interpret that value. A sentence that adds “higher than most members of Group Y” supplies a population comparison. A sentence that adds “meets the stated threshold for Domain Z” supplies a criterion relation. The extra words change the claim being made, not necessarily the score that was calculated. This separation helps when a report places multiple labels beside one result.
This classification describes the interpretation’s comparison point. It does not tell you whether the measure is reliable, whether the group or criterion suits your situation, or whether the conclusion is useful for a particular decision. Those are separate questions. Reports also vary in how precisely they use these terms: “above average,” for instance, suggests comparison but does not identify the group or distribution. If the sentence and supporting material do not disclose whether the reference is a population or a defined criterion, the responsible classification is unresolved. Do not force an unclear statement into either category merely because its layout resembles a familiar score report.
Sources: NCME Assessment Glossary
What does a percentile actually compare?
A percentile locates a score within a specified score distribution. It does not say what percentage of a personality trait someone has. The NCME Assessment Glossary defines percentile rank in relation to the percentage of scores in a specified distribution that fall below a score. So a report sentence such as “Your score is at the 80th percentile” is incomplete unless the reader can identify the distribution behind that position. The percentile is a comparison result, not a second name for the underlying score.
Consider this hypothetical sentence: “Your score on Scale X is at the 80th percentile compared with adults in Group Y.” To interpret it, a reader needs to know what Group Y means, which version and scale produced the score, and what score distribution supplied the comparison. If the report instead says only “80th percentile,” the number alone cannot reveal whether the reference consisted of a broad population, a selected subgroup, users of one version, or another defined sample. These details are not decorative. Change the reference distribution and the same score can occupy a different relative position. A useful description should let the reader trace both the assessment form and reference group instead of treating a percentile as a property that travels unchanged across versions or samples.
The underlying raw score and the percentile therefore answer different questions. The raw score records the result under the assessment’s scoring method; the percentile expresses its position relative to a reference distribution. It is not an 80-percent estimate of a trait, an 80-percent chance of behaving in a particular way, or proof of a practical strength. Those meanings would require additional evidence and an explicitly supported interpretation. Likewise, an “above average” label needs a stated average for a specified group before it communicates relative standing clearly.
A well-described percentile can still be useful: it tells the reader how a score compares with a defined set of scores. Its reach ends there. It does not establish that the comparison group resembles the reader, that the difference matters in daily life, or that the person has met a behavior standard. For a personality report, inspect the population, measure version and scale, and distribution attached to the percentile claim. If one is absent, ask the publisher what reference it used; until then, the number’s comparative meaning remains underspecified.
Sources: NCME Assessment Glossary
What makes a band or cutoff criterion-referenced?
A band is criterion-referenced when its categories describe performance or a score’s relation to a defined domain, standard, or rule. The NCME Assessment Glossary defines criterion-referenced interpretation by reference to a criterion domain. A label such as “meets the stated description” can therefore communicate a criterion judgment if the description specifies what is being judged. By contrast, a label that locates a score in a percentile band reports relative position within a score distribution. A low, middle, or high band does not explain its own basis: the report must show whether those boundaries refer to other respondents, a defined domain, or another rule.
Hypothetical contrast: Criterion-style: “This response pattern meets the report’s stated description of the ‘consistent planning’ category.” Norm-style: “This score falls in the upper band of scores for the report’s specified comparison group.” The first ties a category to a described domain; the second places a score within a group’s distribution. These are examples of different interpretive claims, not labels for actual test results. The word “band,” a color zone, or a dividing line on a graphic cannot settle which claim is being made. A threshold tells the reader that some boundary has been set. It does not, by itself, name what the boundary means.
It also helps to separate how a boundary was selected from how it is later used. A publisher might consult data from a reference group when choosing a numerical threshold, then use that threshold to assign a person to a category defined by a behavior domain. The threshold’s development may be informed by norms or empirical observations; the resulting statement may still be criterion-style if it interprets the score against the stated domain. Conversely, a report may divide scores into bands while leaving the comparison distribution or rationale unstated. In that case, the visible cut points do not establish that the bands represent either a population rank or a meaningful behavioral standard. Read the documented interpretation and the procedure for setting the boundary as related but distinct pieces of information.
A criterion is not automatically objective or self-justifying because it has a name and a cutoff. Someone has to define the domain, decide what observations count, and select or defend the rule used to draw its boundary. A threshold may be empirically chosen, but evidence that a number can separate cases does not alone explain why the chosen category is important for a particular purpose. For a reader, the useful distinction is modest: ask what the category is intended to describe, and whether the report connects the cut point to that description. The classification tells you the kind of interpretation being offered; it does not prove that the cutoff is a natural dividing line or that acting on it is warranted.
Sources: NCME Assessment Glossary
What does the TIPI example show—and not show?
The Ten Item Personality Inventory (TIPI) makes the distinction concrete because its scoring instructions and norm materials can be inspected separately. In “A Very Brief Measure of the Big-Five Personality Domains,” the TIPI is a ten-item measure with two items for each broad Big Five domain. For each domain, the scoring method combines one item with the oppositely keyed item after reverse-coding it, then averages the pair. This produces a scale score under the instrument’s scoring rule. It does not, by calculation alone, say whether the result is typical compared with a population or meets a defined behavioral standard.
Here is an illustrative path, with no respondent result implied: take the two item responses assigned to one domain; reverse-code the oppositely keyed response as directed; average the two values to obtain that domain’s TIPI score. That average describes the output of the scoring procedure. A separate optional step could compare the score with a documented reference distribution and report a standardized score or percentile. That added comparison answers a different question: where the score falls relative to that reference. The comparison requires the specific norm source and its scoring conventions; it is not contained in the two-item average. Nor does the mere existence of a norm table turn the scale score into a behavior standard. A report must state what comparison it actually makes.
“A Very Brief Measure of the Big-Five Personality Domains” reports a development and evaluation program that examined the TIPI using self, observer, and peer reports, test-retest evidence, and predicted external correlates. The authors report useful convergence with other personality measures and retest evidence, alongside comparatively weaker reliability or correlations than longer measures in several comparisons. Their discussion also identifies a meaningful design tradeoff: with only two items per broad domain, the measure cannot provide the facet-level distinctions that longer inventories may assess. These findings support treating the TIPI as a very brief measure with evidence worth considering, not dismissing it as meaningless solely because it is short. They also constrain how fine-grained an interpretation can be. A two-item average offers limited coverage of a broad domain, so a precise individual-level narrative would need support beyond the arithmetic itself.
Norm provenance adds another layer. The TIPI developer page identifies its listed supplemental norms as unpublished data collected through an online music-preference study and provides a separate demographic-information link. That description gives a reader a source to investigate; it does not establish that the reference group represents every reader or suits every report purpose. A norm comparison is only as interpretable as the information available about the reference and the way the score was produced. Do not silently treat these supplemental norms as a universal population benchmark, or assume that a provider using the TIPI uses this same reference.
Likewise, the existence of a norm table and published evaluation does not certify every online implementation. A web report may use a different translation, scoring procedure, sample, display, or added category. The original TIPI study evaluates its measure in its own research settings; it does not validate every report that borrows the inventory, its individual conclusions, or a hiring threshold. The evidence supports a bounded reading: the item average is the score calculation; a named norm source can add a relative comparison; and neither step on its own establishes a criterion for behavior or an employment decision. If a report supplies both a score and a label, its own documentation must connect those elements.
A careful reader should therefore keep three objects distinct in this example: the paired-item calculation, any comparison against a reference distribution, and any category attached by a particular report. The TIPI developer instructions establish how the scale pair is scored; the supplemental norm note identifies one possible source for comparison; neither document says that every provider must display the same norm-based interpretation. If a report presents a band or conclusion beyond those documented elements, that is an additional claim to trace to that report’s own method. This distinction prevents an instrument name from standing in for missing information about a specific score display.
Sources: A Very Brief Measure of the Big-Five Personality Domains (Gosling, Rentfrow & Swann, 2003); Ten Item Personality Measure (TIPI), developer page
How can one score acquire two interpretations?
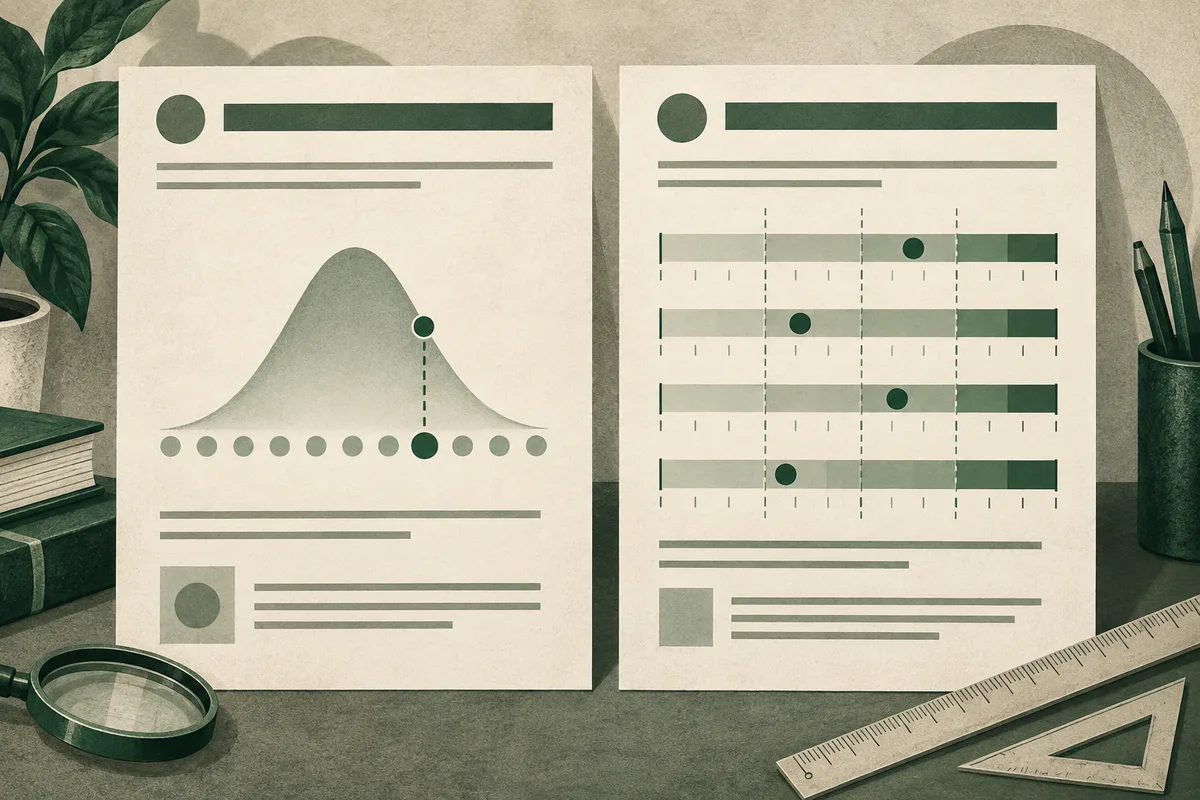
Yes. One calculated score can support both a norm-referenced display and a criterion-referenced statement, provided each comparison is described and supported on its own. The number need not change: what changes is the question asked about it. A norm comparison asks where the score sits in a specified distribution. A criterion interpretation asks how it relates to a defined domain, standard, or operational rule. Neither label cancels the other, and the presence of both does not make either one self-explanatory.
Imagine a hypothetical report that calculates a score of 24 on Scale X. It might state, “24 is above the median in the report’s specified reference sample.” That is a relative-position claim. The same report might separately say, “Under this report’s published rule, scores of 22 or higher meet its defined planning-description threshold.” That second sentence applies a rule to a domain. These are invented examples, not actual test results or recommended cutoffs. The first helps answer how the score compares with that sample; the second says whether it crosses the report’s stated boundary. A reader should not translate “above the median” into “meets the standard,” or the reverse, because the two statements use different reference points.
The Inquisit Ten-Item Personality Inventory (TIPI) Technical Manual illustrates the display side: its documentation describes one TIPI implementation reporting standardized scores and percentiles against selected norms. That shows how an implementation can add a population comparison to a calculated score. It does not establish that this vendor or every TIPI report also makes a criterion claim. To establish a second interpretation, the report would need to specify the domain or rule it applies and explain what its resulting category means. The instrument’s name or score alone cannot supply that missing description.
An assessment may transparently offer a norm interpretation, a criterion interpretation, both, or neither. A bare score may have no stated comparison at all. When both appear, inspect their documentation independently: the norm statement needs an identifiable reference distribution, while the criterion statement needs a defined domain and an explained boundary. Two labels do not show that a score is interchangeable across settings, that the same rule travels to a new population, or that the criterion boundary is defensible. Mixed reporting resolves the apparent either/or at the level of interpretation; it does not make every attached claim equally well supported.
Sources: Standards for Educational and Psychological Testing (AERA, APA, NCME), official site
Does classification settle whether the report is fit for its use?
No. Identifying a report’s comparison type tells you what relation its sentence describes; it does not establish that the interpretation is accurate, useful, or appropriate for your decision. Classification is a first reading step, followed by a separate question: what evidence supports this meaning for this population and purpose? The distinction matters because an interpretation can be clearly norm-referenced yet use a group that is a poor fit for the question at hand. A criterion statement can name a domain and threshold clearly while offering little justification for why that boundary should guide the proposed action.
For example, a clearly identified norm group might be relevant to describing relative standing among that group, but not to deciding whether a person will thrive in a particular role. That further inference would need evidence connecting the measure and its interpretation to the role-related conclusion. Likewise, a defined criterion such as “meets the planning description” makes the comparison legible, but clarity about the wording does not show that the rule was developed well or that crossing it matters to the reader’s decision. These are distinct gaps: relevance concerns the match between the reference and purpose; support concerns whether evidence warrants the interpretation drawn from it.
The Professional Practice Guidelines for Occupationally Mandated Psychological Evaluations, APA, gives a bounded example of the further scrutiny required in a consequential setting. It says psychologists should rely on tools validated for a population appropriate to the evaluation and use assessment techniques for purposes appropriate to their supporting research. This guidance concerns occupationally mandated psychological evaluations; it should not be recast as a universal legal rule for every consumer report. Its practical implication for a reader is narrower: when an assessment is used in a consequential work evaluation, ask whether evidence supports the particular tool, population, and purpose at issue, rather than treating the presence of a norm group or named criterion as sufficient assurance.
For private reflection or coaching, a report may still prompt a useful, limited question even when it cannot support a high-stakes individual decision. Someone might use a described pattern to notice how they plan or collaborate, then check whether that observation fits their experience. That modest use does not require treating the report as a verdict. By contrast, using a score to screen, rank, hire, promote, or make another consequential employment decision calls for evidence appropriate to that proposed use and careful attention to the decision process. This is not a full guide to selection testing; it marks why the intended use changes what evidence a reader should request.
A practical sequence is therefore: identify the comparison, then inspect the evidence for the interpretation and the proposed purpose. A norm label is not a validity certificate, and a criterion label is not proof that its threshold deserves action. The counterpoint is that limited support for a consequential claim need not erase every reflective use: suitability is purpose-specific. Classification helps prevent one kind of misreading, but it cannot certify fitness.
Sources: Professional Practice Guidelines for Occupationally Mandated Psychological Evaluations, APA
What if the report leaves the comparison unstated?
If a report gives a percentile, band, or cutoff but does not identify what the comparison refers to, classify that particular statement as unresolved. The missing reference has not been established from the material you can see; that does not show the claim is false, or that the publisher has no supporting documentation. The information may sit in a technical manual, scoring guide, or version-specific note that the brief report does not reproduce. A familiar graph or polished label cannot fill in the missing definition by itself.
Ask about the sentence you actually need to interpret. A concise request can read: “I’m looking at the [report name and version, if shown]. What does the statement ‘[quote the exact band or percentile sentence]’ mean? Please point me to how the score was calculated and, for this statement, the comparison population or criterion domain it uses. If it assigns a band, how were that band’s boundaries chosen? What interpretation is the report asking readers to draw from this sentence?” This keeps the request tied to the visible claim. For a percentile, the population and score reference are central; for a criterion label, the domain and boundary explanation matter. You need not demand unrelated technical details to clarify one displayed statement.
If the publisher replies with a manual or documentation, check that it covers the same report version, score, and interpretation rather than assuming a general document answers every question. The useful response links the sentence to its scoring and reference basis, and explains how the displayed category follows from them. If the report uses a named comparison but does not explain a boundary, you may understand the kind of comparison while still lacking the reason for that particular cutoff. Keep those unanswered pieces separate instead of treating a partial reply as full support.
If no answer arrives, record the claim as unverified for your purposes and avoid decisions that depend on it. You can still read the rest of the report where its meaning is clear, or use a plainly described observation as a prompt for reflection. A nonresponse is not evidence that the hidden comparison is wrong; it simply leaves you without enough information to rely on that statement. The conclusion can change if relevant documentation becomes available and matches the report version and claim.
How do I test what the interpretation means in daily work?
Use a report category as a question to examine in context, not as a permanent identity or verdict about which work you can do. Translate the wording into a specific behavior you can notice, then look for situations where it appears and situations where it does not. This exercise can make a broad statement more useful for self-reflection, but it cannot establish how the assessment was scored or what reference supports its original interpretation.
Illustration (invented): imagine a report says, “You prefer independent work.” Instead of adopting that as a fixed description, ask what “independent” means in observable terms. Do you begin more readily when you can set your own sequence? Do you concentrate better during uninterrupted drafting, while still wanting a colleague’s review before a decision is final? Notice the setting, task, degree of choice, and kind of interaction. The point is not to prove the sentence true by finding one matching day. It is to learn what narrower pattern, if any, recurs under identifiable conditions.
Look deliberately for a counterexample. Perhaps you enjoy solo work on familiar tasks but seek frequent collaboration when the problem is new, the stakes are high, or responsibilities are shared. Perhaps a quiet environment helps with analysis while discussion helps you generate options. Those observations do not cancel each other; they may show that the original label compresses different tasks into one phrase. You can then replace “I am independent” with a question such as “Which tasks benefit from uninterrupted time, and when does collaboration improve the result?” That is a more useful prompt for a work decision because it points toward conditions to compare, rather than assigning a role or predicting success.
A brief note can keep the inquiry grounded: record the task, who was involved, the amount of choice or structure, what you did, and what helped or hindered the work. Compare a few distinct situations before treating a pattern as recurring. This is personal observation, not a formal validation exercise; it cannot verify the report’s norm group, criterion, or psychometric quality. If the conclusion could affect a consequential work decision, your notes should not stand in for evidence that the assessment supports that use.
If you want a structured prompt for this kind of low-stakes reflection, the live [100-item Work Pattern Report assessment](https://personalityreport.org/assessment) asks about work patterns across ten continuums. Its result is for personal reflection; it supplies no norm, cutoff, type, selection score, or job recommendation. It can help you put observations about how you decide, plan, collaborate, handle conflict, adapt, or learn into a more organized frame. It cannot identify the reference behind another report’s percentile or band, and it should not be used to decide who should be hired, promoted, or assigned a role.
What should I do with this report now?
If the report names a comparison population and explains the score’s position within it, use the result only to describe relative standing in that group. If it defines a domain and rule, read the result against that stated criterion. When the reference is missing, mark the interpretation unclear and ask the provider for documentation tied to the exact report version and sentence; withhold any conclusion that depends on the missing comparison. For a personal reflection, copy the report’s exact sentence and note one real situation in which the described behavior appeared—or did not. If someone else may use the result for a consequential decision, ask that person or the provider what evidence supports this interpretation for that purpose before relying on it. Keep your note tied to the situation, rather than turning a single instance into a general label. If you want a low-stakes prompt for concrete observations about how you work, you can explore the [100-item Work Pattern Report](/assessment), which asks about ten work-pattern continuums. It may help you frame a reflection of your own; it does not identify whether another report is norm-referenced or criterion-referenced.
Questions readers ask
Can a personality report be both norm-referenced and criterion-referenced?
Yes. A percentile may describe relative standing in a specified reference group, while a separate category applies a defined domain or rule. Assess each statement on its own.
Does a percentile tell me how much of a personality trait I have?
No. It describes a score’s position within a specified distribution, not the percentage of a trait. Check which population and score distribution the report uses.
Sources and notes
- NCME Assessment Glossary
Authoritative definitions distinguish norm-referenced interpretation (comparison with a specified reference population distribution) from criterion-referenced interpretation (relationship to a defined criterion domain); it also defines norms, percentiles, user norms, and cut scores.
- A Very Brief Measure of the Big-Five Personality Domains (Gosling, Rentfrow & Swann, 2003)
Original TIPI development and evaluation paper; supports a worked example of score construction and norm tables and reports convergent, test-retest, external-correlate and observer evidence alongside the limits of a 10-item measure.
- Ten Item Personality Measure (TIPI), developer page
Developer instructions average an item and reverse-coded item for each TIPI dimension and identify the listed norms as unpublished 2014 data collected through an online music-preference study, with a separate demographic-information link.
- Inquisit Ten-Item Personality Inventory (TIPI) Technical Manual
Documents one software implementation's scoring and display of standardized scores and percentiles against selected published TIPI norms; this illustrates that a vendor's implementation and comparison reference must be identified.
- Standards for Educational and Psychological Testing (AERA, APA, NCME), official site
Joint publisher identifies the Standards as guidance for educational and psychological testing; use as the authoritative standards framework for asking whether interpretation evidence and use are documented, not to claim the Standards certify any named report.
- Professional Practice Guidelines for Occupationally Mandated Psychological Evaluations, APA
APA guidance states psychologists should select and rely on tools validated for a population appropriate to the evaluation and use assessment techniques for purposes appropriate to the supporting research; applies to occupationally mandated evaluations, not every self-reflection context.
- 100-item Work Pattern Report assessment
Direct provider description of the live report as a low-stakes self-report for personal reflection across ten work-pattern continuums; no norm, cutoff, type, or selection score is supplied.
Apply it to your work
Turn a work-style question into observable patterns
From this guide: If a report leaves you wondering how a tendency appears in a real work decision, compare it with specific situations and look for where it does and does not fit.
A norm or criterion label explains how a score is interpreted; it does not show how a tendency appears in your work. The Work Pattern Report offers a low-stakes prompt to reflect on decision and collaboration patterns across ten continuums. Use it to frame concrete observations about your work, not as a job recommendation or selection score.