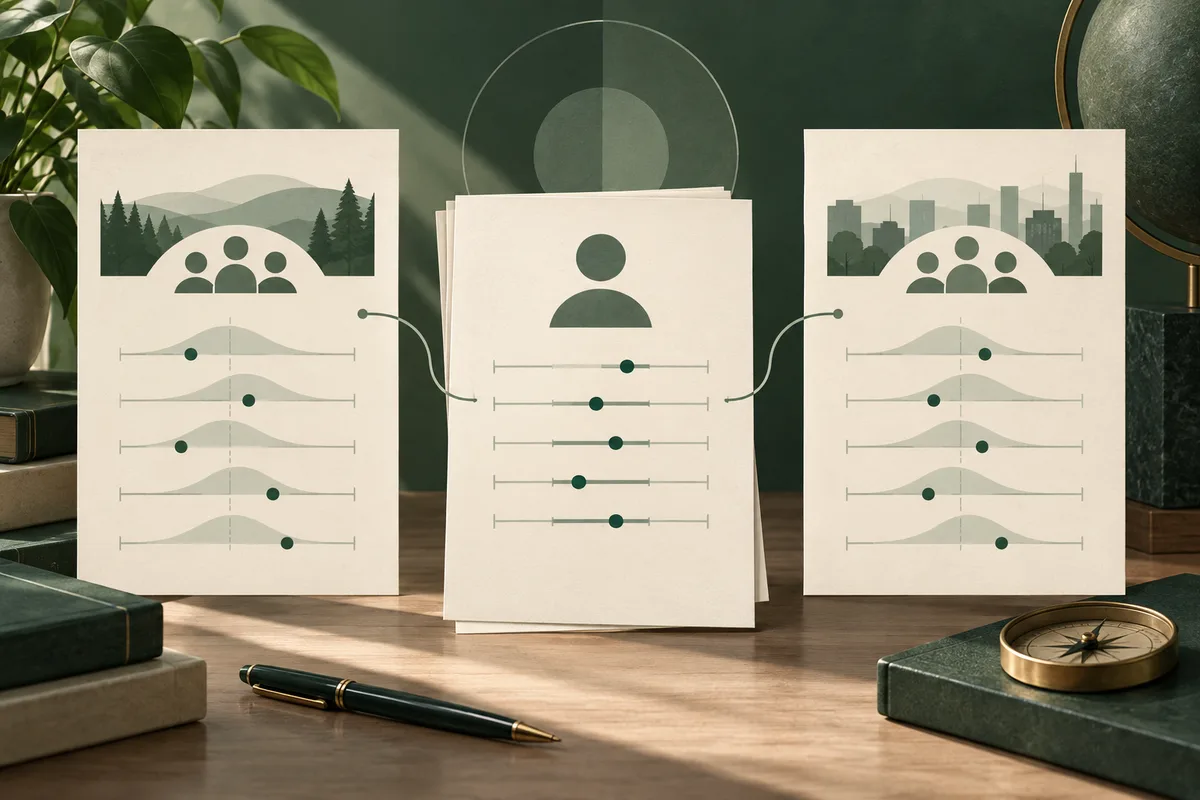
When the same assessment, responses, scoring rule, and raw score are compared with a different norm group, relative standing—and any label derived from it—can change. That does not by itself show that a person’s tendency changed or justify rewriting its description. Revise broader interpretation only when evidence supports the new population and intended use.
What exactly changes when the norm group changes?
If the instrument, version, responses, scoring rule, and raw score stay fixed, changing the norm group can change a person’s relative standing. A raw score is the result produced by the scoring rule; it is not automatically a percentage of a trait. A percentile rank locates that score within a defined group. The 2014 Standards for Educational and Psychological Testing define a norm group as a comparison group and describe percentile rank in relation to that group. The Australian Psychological Society’s guidance also explains that norms come from samples drawn from an intended population. Together, these definitions show why a new percentile is a new comparison, not evidence that the person’s answers or tendency changed. Imagine, hypothetically, the same raw result compared with two differently shaped score distributions. Its position could differ between them, although the person and result remain fixed. This illustration explains relative position; it does not describe a particular assessment or an actual report. A changed percentile may also change a band if that label is set by percentile cut points. But a band might follow a different rule, so words such as “average” or “high” do not reveal their own calculation. Publisher rules for boundaries and tied scores can affect exact labels. Check the report’s scoring notes to see which fields depend on the norm distribution. Keep comparison language separate from behavioral description. “Higher than this reference group” is relational and can change when the group changes. A sentence describing a tendency is a further interpretation; a new percentile does not mechanically rewrite it. Whether that description remains appropriate for a new population requires evidence about the instrument and the intended question. Therefore, accept a changed percentile as a changed statement about relative position, while withholding the conclusion that the person has become more or less of a tendency. Ask which field changed, which group it references, and what rule produced any band. Then consider the descriptive claim separately.
Sources: Standards for Educational and Psychological Testing; Psychological tests and testing
What is a fair same-score comparison?
To isolate the effect of a comparison group, hold the assessment version, items, responses, scoring rule, administration, and raw score constant. Then compare only outputs that depend on the norm group. If any input changed too, the reports cannot show that the norm change alone caused the difference.
A raw score is generally calculated from responses under a scoring rule; a norm-referenced result locates it against a comparison group. The ETS Standards for Quality and Fairness defines a norm group as a group used as a comparison basis and describes norms as performance data that may be expressed as percentile ranks. Thus one fixed raw score can correspond to a different percentile or transformed standard score when the reference distribution changes. That does not mean the raw score or the person's responses changed. Some reports do not show raw scores, so ask the provider which field stayed fixed.
Four changes can confound this comparison. A revised inventory or translation may change the version or item wording. A retest supplies new responses. A changed scoring key, may alter the raw result. And a report may move from norm-referenced language to a criterion-based judgment or descriptive account. These answer different questions: comparison with a group is not the same as meeting a stated criterion. The ETS standards treat norming, scoring, and reporting as distinct parts of test practice, which helps readers locate what changed instead of attributing every new label to the norm.
First compare version, items, answers, scoring instructions, and administration conditions. Then name each reference group and mark which fields changed: raw score, standardized score, percentile, or category. A label such as “average” is not self-explanatory; it may rely on a norm-based range or another provider rule. The ETS standards call for clear score communication and documentation of sampling details that may affect interpretation. Ask the provider which population supplied the norms, what scoring basis produced each field, and whether other inputs changed.
If only the reference distribution changed, read the new percentile as a different relative comparison. If the version, responses, scoring, or administration also changed, request a score-level explanation before attributing the revised narrative to the norm group. If the inputs are unclear, treat the cause as unresolved.
Sources: Standards for Educational and Psychological Testing; Psychological tests and testing
Which parts of report language move with the norm?
These report outputs answer different questions. A raw score records the result under the test’s scoring rule. A norm-standardized score expresses that result on a scale defined using a reference distribution. A percentile locates the score relative to people in the named norm group. A descriptive band, such as “average” or “high,” assigns a label according to a rule that the report should make clear. Only some outputs necessarily depend on the comparison group. The *ETS Standards for Quality and Fairness* define norms as performance data for a group used to interpret scores; the Australian Psychological Society’s *Psychological testing* guide likewise explains that norms let a reader compare a result with a specified population. A percentile therefore means relative standing in that group. It does not mean the person has that percentage of a trait, nor does it describe change over time. If the norm distribution changes while the raw score stays fixed, the percentile can change because the comparison has changed. A standardized score also needs its scoring notes. If its scale is norm-based, the same raw result may map to a different standardized value under a different norm system. The report should identify how the scale was created; similar-looking values are not automatically comparable. A raw score, by contrast, may remain fixed when only the norm table changes, provided the instrument, responses, and scoring rule are unchanged. Some reports do not display raw scores. A band is less self-explanatory than it sounds. “Average” might be assigned from a percentile range, a standardized-score interval, a raw-score threshold, or another stated provider rule. The APS guide describes classifications as linked to score ranges, but cannot identify the rule used by a particular report. The label may move if its cut points are norm-derived; it may stay put if the rule is independent of the norm. Do not infer the rule from the label alone. When two readings differ, trace each changed sentence to its score field and rule. Ask which fields depend on the norm, how band boundaries are set, and whether the group matches the intended comparison. Until that is clear, accept a changed percentile as a changed relative comparison; treat a changed band as unresolved; and do not treat either change, by itself, as proof that the underlying tendency changed.
Sources: Standards for Educational and Psychological Testing; Psychological tests and testing
When is the new group a better comparison?
A norm is more useful when its target population and collection conditions match the question the report is meant to answer. A specific group label does not by itself make a comparison more representative or relevant. Ask what population it describes and why that population fits this interpretation.
Check whom the norm is intended to represent, how participants were recruited, when data were collected, which language and test version they used, and whether the publisher reports participation or weighting. The COTAN Review System for Evaluating Test Quality says representativeness requires a defined population and sampling information; sometimes documentation does not even identify the target.
Sample size and relevance answer different questions. More observations can reduce random variation in an estimated distribution, but cannot automatically fix a mismatch between the sample and the population named. A broad norm may fit a broad descriptive question. An occupational norm may fit a comparison within that setting if its recruitment and coverage support the use. This distinction is a practical inference, not a claim that one kind is always superior.
The 2015 review A Comparative Review of Current Practices in Personality Assessment Norming reviewed norms for 30 assessments offered in the United States, United Kingdom, and Canada. Its abstract emphasizes accurate, representative norms for interpreting individuals against a norm group. It does not establish that any named assessment has a representative sample, so instrument-specific documentation remains necessary.
The Use of Personality Test Norms in Work Settings: Effects of Sample Size and Relevance gives a bounded example. It analyzed Hogan Personality Inventory data from five sales and four trucking samples, with sizes from 394 to 6,200. The authors reported that samples above 100 had little practical impact on norm-score reliability, while profiles varied across norm samples. Average T-scores differed by 7.3 points between sales and trucking norms, about 14 percentile points. This result concerns that instrument and those work samples, not other reports. They show why adding observations and choosing a relevant reference are separate decisions.
Choose a reference group by the comparison question, not by which percentile feels more favorable. If the report gives only sample size or a broad label, confidence in population-relative wording should remain limited. Ask the publisher for the target population, collection method and date, and the interpretation supported by the evidence. A fitting norm can clarify relative standing; it cannot alone prove a broader description of the person.
Sources: A Comparative Review of Current Practices in Personality Assessment Norming; Standards for Educational and Psychological Testing; The Use of Personality Test Norms in Work Settings: Effects of Sample Size and Relevance; COTAN Review System for Evaluating Test Quality
When does a different group call for a different trait explanation?
A changed comparison group alone calls for recalculating relative standing, not automatically rewriting what the measured tendency means. A broader explanation may need revision when the original wording depended on a poorly matched population, or when evidence does not support carrying that interpretation into the new group and use. A different percentile is not that evidence. Separate four levels of statement. First is an individual score’s location within a named distribution. Second is a descriptive account of the scale, such as what a higher response pattern is intended to represent. Third is a claim that one group differs from another on average. Fourth is a prediction or action based on the score. Each step adds an inference. Rank is relative position in a reference distribution; a trait description assigns meaning to measured responses; a group comparison says something about populations; a prediction connects scores to an outcome. The latter statements cannot be derived from a percentile alone. The Standards for Quality and Fairness describes validity for intended interpretations and uses, with evidence relevant to the intended population. In plain terms, validity is evidence supporting a particular interpretation for a particular purpose and population. It is not a permanent seal attached to a test name. If a report moves from self-reflection to coaching, or to selection, the evidence must support that use as well as its descriptive wording. A changed norm does not turn a general personality report into a diagnosis, and a norm-based label alone cannot establish a consequential prediction. Suppose, as an illustration, the same responses receive a different relative label after the publisher adopts a comparison group that better matches the report’s stated audience. The rank may be recalculated. The scale’s intended description need not change if the instrument supports that wording for the relevant respondents and context. But if the earlier description was presented as typical of a population the norm did not represent, its scope should be narrowed. Choosing a group with a closer demographic label does not establish that every item or interpretation works comparably there; that requires evidence about the measure and groups at issue. The practical question is not “Which label is the real personality?” but “What supports this sentence beyond the new norm table?” Ask which statements are norm-dependent, what population the norm represents, and what evidence supports the descriptive language for that population. Keep the tendency provisional and bounded to the scale. A changed reference can improve comparison relevance; it does not, on its own, rewrite the person.
Sources: Standards for Educational and Psychological Testing; Psychological tests and testing
What does measurement comparability add beyond a new percentile?
A percentile answers a relative question: where does this score sit in a reference distribution? It does not establish that an instrument measures the same tendency in the same way across groups. Researchers examine measurement invariance: whether a specified measurement model functions similarly across specified groups using a particular instrument and version. This is evidence about comparability, not a certificate attached to a trait name. A new norm can recalculate relative standing; invariance evidence helps determine whether a broader group comparison is interpretable. In common factor-model tests, the levels build on different assumptions. Configural invariance asks whether the same broad pattern of items and factors appears in each group, supporting a limited claim about similar structure. Metric invariance asks whether item loadings, the links between items and the measured factor, are sufficiently alike; this supports comparing relationships involving that factor. Scalar invariance additionally asks whether item intercepts align, so people with the same underlying level would be expected to have comparable item scores. That condition is generally needed before comparing latent group means. Strict invariance adds equality of residuals, or item-specific unexplained variation, and concerns stronger comparisons of observed scores. Passing one level does not imply passing every level; a result applies only to the groups, model, version, and sample tested. The 2020 systematic review, “Are Personality Measures Valid for Different Populations? A Systematic Review of Measurement Invariance Across Cultures, Gender, and Age,” examined 95 studies from 75 peer-reviewed articles. In those studies, none established scalar or strict invariance across cultural or ethnic groups; some did establish those levels across gender or age groups. The review also reported that results varied with the number of groups tested. This warns against assuming evidence for one group pairing transfers to another. It does not show that every personality measure fails for every cultural comparison: the result describes the included literature and its tested samples, not an unnamed report. A lack of full scalar invariance does not make every individual description meaningless. The review concerns evidence for specified group-level comparisons; weaker levels can support narrower questions, and a reader’s low-stakes reflection on a personal pattern is not the same claim as a difference between group averages. The ETS Standards for Quality and Fairness advises supporting intended interpretations and actions for intended populations and considering plausible alternatives. Applied here, if a report moves from describing one person’s tendencies to saying one group tends to score higher than another, ask for evidence on that exact instrument and those groups. Do not infer a group difference from changed percentiles alone or transfer findings from a different test or comparison.
Sources: Are Personality Measures Valid for Different Populations? A Systematic Review of Measurement Invariance Across Cultures, Gender, and Age; Standards for Educational and Psychological Testing
What is the strongest case for changing more than rank?
There is a sound reason to revise more than a percentile when the old reference group could not support the report’s original interpretation, or when evidence about the measure changes what its scores can mean for a new group. Imagine a report designed to describe responses relative to one language version and population, then reused for people answering a translated version in a different setting. A newly suitable norm could make the relative comparison more relevant, while questions about whether the items carry the same meaning remain open. The first issue concerns where a score sits in a distribution; the second concerns what the score represents. A replacement norm addresses the first directly. It cannot, by itself, settle the second.
That distinction matters because people may understand a phrase differently, encounter different situations when answering, or use response options in different ways. These are possible explanations to investigate, not assumptions about any culture or group. Evidence would need to identify the instrument version, groups compared, item or response patterns, and the interpretation being claimed. In the 2020 systematic review of personality-measure invariance across cultures, gender, and age, 95 studies from 75 peer-reviewed articles were included. None of the reviewed studies established scalar or strict invariance across cultural or ethnic groups, while some studies did establish those levels across gender or age groups. The authors also found that studies comparing more groups tended to report lower invariance. This review signals that comparability findings can depend on the groups and design examined; it does not show that every personality measure fails for every cross-cultural use, or establish what is true of an unnamed report.
A 2026 scoping review, “Understanding and Assessing Personality Across Cultures,” also found uneven evidence across instruments and cautioned against inferring average personality differences between cultures without scalar invariance. Its 233 publications came from a defined search. Some measures performed better in particular cultures. Weak evidence for one broad comparison does not erase every narrower description or within-group use. The ETS Standards for Quality and Fairness say interpretations and uses should be supported for intended populations, and sampling details that affect interpretation should be described. Together, these sources support a limited conclusion: revise the claim whose evidence or scope has changed, and retain other wording only where its support remains adequate. A norm table alone cannot demonstrate equivalent item meanings; uncertainty about group-level comparisons does not prove an individual reflection prompt is useless. A broader rewrite needs documentation for the relevant version and groups, evidence about item function, and a clear account of which interpretations that evidence supports.
Sources: Are Personality Measures Valid for Different Populations? A Systematic Review of Measurement Invariance Across Cultures, Gender, and Age; Understanding and Assessing Personality Across Cultures: A Scoping Review; Standards for Educational and Psychological Testing
How much can score uncertainty change the practical reading?
A percentile can move when the norm group changes, but its practical importance depends on score precision and the rule that turns scores into labels. If uncertainty reaches across a category boundary, the new label may sound more decisive than the measurement warrants. It changes the report’s comparison, but does not automatically show a meaningful change in the person. Keep three questions separate. Reliability concerns consistency under specified conditions; measurement error is uncertainty around an observed score; validity concerns support for a particular interpretation and use. The Standards for Educational and Psychological Testing ties validity to intended interpretations and actions. A standard error of measurement estimates uncertainty under a stated model and assumptions. A confidence interval uses that estimate to describe a range of plausible scores. There is no responsible generic interval for every personality report. Ask whether its estimate applies to this score and norm group. The Australian Psychological Society’s guidance describes test-specific ranges for classifications. COTAN also notes that sample size alone does not establish representativeness. Percentiles mark positions in a distribution, not equal units of a trait. The same percentile movement can correspond to different raw-score distances in dense and sparse regions. If a small shift changes a band, check its cut-point rule and whether documented uncertainty spans both sides. Score precision concerns the individual estimate; representativeness concerns the reference population. Until both are clear, treat a boundary-crossing label as provisional, and request the underlying score estimate, reference-group description, and classification rule before relying on it in reflection or discussion.
Sources: Standards for Educational and Psychological Testing; Psychological tests and testing; COTAN Review System for Evaluating Test Quality
How should I compare two report readings?
Compare the versions one claim at a time. Record what stayed fixed: assessment and version, answers or raw score, scoring rule, and administration context. Name each reference group and collection date. A norm group supplies the basis for norm-referenced scores; a percentile describes position within that group, not the percentage of a trait. The Standards for Educational and Psychological Testing and the Australian Psychological Society’s guidance support this distinction. A changed comparison is not, by itself, a changed characteristic. Mark the score format beside each changed phrase: raw score, norm-standardized score, percentile, or descriptive band. Ask whether the band uses a norm-based range, raw threshold, or another rule. If the provider does not say, do not assume the label means the same thing in both readings. Ask which rule produced the sentence and whether it changed. For an illustration, imagine the same response pattern is compared with two reference groups and receives different relative labels. This illustrates how distributions can change relative labels; it is not about a particular assessment. Separately, check whether the description prompts notice of recurring situations and exceptions. Those observations can help judge whether wording is useful for reflection. They do not validate the instrument or prove one norm is better. If the sentence goes beyond relative standing, ask for evidence at that broader level. Gaddis and colleagues’ review of norming practices emphasizes accurate, representative norms; the fit of an assessment depends on its documentation. Ask who the norm population represents, how and when it was sampled, which score fields use those norms, and what evidence supports the changed trait description for the relevant group and purpose. Group comparisons and predictions each need specific support. Record the exact changed sentence and its basis. If the provider cannot identify the norm group or scoring rule, limit your conclusion to disclosed score information and avoid population claims.
Sources: Standards for Educational and Psychological Testing; A Comparative Review of Current Practices in Personality Assessment Norming
What should I do next with the changed interpretation?
Treat the new percentile as a new comparison, not as evidence that your personality changed. Write down the version, named groups, changed score fields, and exact sentence. Ask the provider which fields are norm-referenced, how the group was defined and collected, and what rule produced any category such as “average” or “high.” The Standards for Educational and Psychological Testing tie validity to the interpretation and use intended for a score; a changed comparison alone does not support a broader claim about what you will do.
A well-matched, documented norm can support a different statement about relative standing. Revising a wider description of a tendency calls for evidence that the measure supports that interpretation for the relevant group and purpose. Neither makes a general personality report a diagnosis or an employment decision. If the norm or scoring basis is unclear, keep the conclusion narrow: note the reported result and leave the broader explanation provisional.
For low-stakes reflection, choose one described work tendency and compare it with recent situations, including one when it did not appear. Ask what was happening, what you did, and what conditions seemed to matter. This turns a broad phrase into a question to explore; it does not validate the assessment or establish a fixed trait. For prompts about decisions and collaboration, the Work Pattern Report at /assessment offers a low-stakes self-report. It has no norms, cutoff, type, or selection score, and does not recommend a career. Browse /topics for report-literacy guidance.
Sources: Standards for Educational and Psychological Testing
Questions readers ask
Does a different norm group mean my personality changed?
No. If the assessment, responses, scoring rule, and raw score stayed fixed, a changed percentile reflects a different comparison. It does not, by itself, show that your answers or measured tendency changed.
Can a different norm group justify changing a trait description?
Sometimes, but a new percentile alone is not enough. A broader revision needs evidence that the instrument supports that description for the relevant population and intended use.
Sources and notes
- Standards for Educational and Psychological Testing
Defines norm groups and percentile ranks, and addresses support for intended score interpretations and uses.
- Psychological tests and testing
Explains norm-based scores, percentiles, and classifications in relation to samples and score ranges.
- A Comparative Review of Current Practices in Personality Assessment Norming
The publisher abstract reviews norming practices across 30 assessments and emphasizes accurate, representative norms.
- Are Personality Measures Valid for Different Populations? A Systematic Review of Measurement Invariance Across Cultures, Gender, and Age
The publisher abstract summarizes 95 studies from 75 articles and reports differing invariance findings across specified group comparisons.
- Understanding and Assessing Personality Across Cultures: A Scoping Review
Assigned in the validated plan as a cross-cultural review reference; its page was not verified as accessible in the live check.
- Standards for Educational and Psychological Testing
Identifies the joint professional standards and links the open-access 2014 edition.
- The Use of Personality Test Norms in Work Settings: Effects of Sample Size and Relevance
Repository abstract reports HPI norm findings from specified work samples, including differences by norm sample.
- COTAN Review System for Evaluating Test Quality
Professional review framework discusses norm representativeness, score distributions, and why sample size alone does not establish fit.
Apply it to your work
Turn a broad work question into patterns you can observe
From this guide: A report comparison can clarify relative standing, but it cannot tell you how a work tendency shows up across your own decisions and collaborations.
If you want to examine how you decide, plan, handle ambiguity, collaborate, and learn, the Work Pattern Report offers a low-stakes self-reflection prompt across those areas. It is a non-validated self-report with no norms, cutoff, type, or selection score, and it does not recommend a career. Use it to identify observations to consider, not to make an employment decision.