Equal treatment asks whether comparable readers encounter the same stated administration and scoring rules. Fair interpretation also asks whether readers can access the measured construct and whether the score supports the report’s claim for this person, comparison group, and use. Consistent procedures matter, but they cannot establish that a score means the same thing across groups or supports a broader conclusion.
What does fair interpretation add to equal procedure?
Equal treatment asks whether comparable readers encounter the same stated rules for instructions, administration, and scoring. Fair interpretation asks whether those procedures let the intended population show the measured personality tendency and whether the score supports this report’s claim for this reader, comparison group, and use. A uniform process matters, but cannot establish all these conditions. A construct is the characteristic an assessment intends to measure. In a personality report, it might be a tendency in the instrument’s framework; it is not a diagnosis or a complete account of a person. Validity is evidence supporting a particular score interpretation for a particular use. It is not a permanent stamp that makes every report sentence accurate. The Standards for Educational and Psychological Testing treats intended interpretations and uses, evidence, measurement error, and fairness as related but distinct parts of test evaluation. Ask: were rules applied as stated, and does evidence warrant this conclusion? Fairness follows a chain: an assessment is designed around a defined construct; people have a meaningful chance to respond to what it measures; scoring follows the stated method; and the report’s claim fits the evidence and intended use. A break at one link changes what can reasonably be concluded, even if everyone received the same instructions and scores were calculated consistently. Consistency alone does not show that the process measures the same thing for everyone or that a score justifies a broader claim. Equal procedure does not mean every reader must interact identically. An access adjustment may help someone respond to intended content without changing what an item asks or how its answer is scored. Whether a change preserves score meaning depends on the instrument and adjustment; “accommodation” alone settles neither question. The Standards for Educational and Psychological Testing discusses equitable treatment and access alongside validity of interpretation and use. The NCME Code of Fair Testing Practices in Education frames fairness as a responsibility across testing, though its scope is educational testing. When a report says a score indicates a tendency, ask whether administration and scoring followed their rules, then whether the report explains the comparison and use that make the statement meaningful. Consistent procedure answers only the first question. It does not turn a tendency into a fixed identity, establish a diagnosis, or support an employment conclusion.
Sources: Standards for Educational and Psychological Testing; Code of Fair Testing Practices in Education
When can identical treatment create an irrelevant barrier?
A shared format can still disadvantage a reader if it adds a demand unrelated to the personality tendency the assessment intends to measure. An adjustment may improve access when it removes that irrelevant demand while preserving the intended measurement. A different access route does not, by itself, make a score unfair or incomparable. The question is whether the adjustment changes the evidence the score represents. Construct-irrelevant variance means score influence from something outside the intended construct. If a personality questionnaire is intended to capture a tendency such as preference for planning, but an inaccessible visual layout makes it difficult for a reader to perceive the response choices, the layout may affect answers for a reason unrelated to that tendency. A confusing translation could create a similar problem if readers interpret an item differently because of wording rather than because their underlying tendency differs. Identical screens and instructions would not remove either barrier; they could reproduce it consistently. The 2026 chapter “Realizing Fairness Through Accessibility for All Test Takers and for Specific Groups,” in Educational Measurement, describes accessibility as an unobstructed opportunity to demonstrate the measured construct. It connects fair interpretation with maximizing relevant information and reducing influence from irrelevant characteristics or testing conditions. Its scope matters: the chapter focuses on educational assessments and explicitly does not directly address personality or employment tests. It offers a parallel framework for asking about access, not evidence that a personality report or adjustment is fair. An adjustment to the route through an assessment differs from a change that could alter what an answer means. For example, making an existing questionnaire compatible with a screen reader may change how choices are presented while leaving item wording, response options, and scoring intact. This is an illustration, not a recommendation for an unnamed test. Rewording an item, changing its response scale, altering timing, or changing scoring could affect interpretation. Whether it does depends on the instrument, intended construct, and adjustment. Ask the provider what evidence supports interpreting results after a change. The Standards for Educational and Psychological Testing treats accommodations that remove construct-irrelevant barriers as part of fairness, alongside design, administration, scoring, and interpretation. The Educational Measurement chapter also describes accommodations as one means of access, and emphasizes accessible design. Neither source establishes a universal accommodation recipe for personality questionnaires. The practical point is narrower: identical administration is not automatically equivalent access, and a different presentation is not automatically a different construct. Consider the adjustment in relation to the specific assessment and score claim. Begin by identifying the feature that interferes: is it the visual presentation, language, an instruction, response options, or another part of the task? Then ask whether the proposed change affects access to the same item or changes the item, response process, timing, or scoring. If the provider has not documented that distinction, ask how the adapted version is interpreted and whether its score can be compared with the standard version. Without that information, neither assume comparability nor conclude that the score is invalid. Keep the interpretation provisional until the missing detail is clear.
Sources: Standards for Educational and Psychological Testing; Realizing Fairness Through Accessibility for All Test Takers and for Specific Groups
What does a score compare—and what does it leave out?
A personality report’s number is meaningful only in relation to its scoring rule and comparison. A raw score results from applying that rule to responses. A percentile rank places it within a specified distribution, indicating the share of scores there that fall below it. It does not say that a person has more of a trait than a stated percentage of all people or give the probability of a behavior. The Standards for Educational and Psychological Testing define percentile rank in relation to a specified distribution, so the reference population is part of its meaning. A standardized score transforms a raw score onto a reference scale. A narrative band, such as “average” or “high,” groups scores under the report’s rules. Raw scores record results; standardized scores express location on their scale; percentiles express relative standing; bands compress scores into labels. None alone establishes whether the instrument measures its intended tendency well or whether a conclusion fits a decision. Trace each number to its scale and comparison. If two norm groups have different distributions, the same raw score can occupy different relative positions. It could fall at one percentile in a broad adult sample and another in a narrower group. This is illustrative, not instrument-specific. Neither percentile is inherently more truthful: each answers a different question. The Standards describe percentile norms as standing within a defined population. The SIOP Principles for the Validation and Use of Personnel Selection Procedures define normative interpretations by their reference group. They reinforce that a norm label depends on its sample. Two instruments may report the same percentile yet measure different constructs or use different norms. Matching labels do not put them on a common scale. Check the version, intended construct, and norm group. Consider an illustration: two readers receive the same percentile for a work-related tendency. One report identifies its version and a relevant reference group. The other gives that percentile but does not identify its norm sample or explain whether it applies. Equal numbers do not make interpretations equally supported. The first permits comparison with a named group, subject to the fit of its norm evidence. The second leaves comparison unresolved. This does not prove its score wrong; the reader cannot judge what it means from the report alone. Precision is another limit. A score is an estimate, and its precision may vary. The Standards discuss standard error of measurement as an estimate of score inconsistency across repeated administrations or parallel forms, typically estimated from group data. Without instrument-specific evidence, do not invent a numerical margin or assume every score is equally precise. Near a category boundary, uncertainty may weaken a sharp distinction between labels; a band can hide uncertainty rather than resolve it. A percentile is not a probability, grade, or prediction. It describes relative standing in a specified distribution; it does not give the chance a person will behave in a certain way, succeed at a task, or fit a role. For self-reflection, it can frame a question about tendencies compared with a defined group, but cannot settle what someone will do. Before accepting “high” or “average,” locate the instrument name and version, norm sample, and statement about when or for whom norms apply. Check the score scale and precision information. If details are missing, the reader cannot fully inspect the comparison or uncertainty. Ask the provider for the missing basis before treating the label as a verdict or comparing reports.
Sources: Standards for Educational and Psychological Testing; Principles for the Validation and Use of Personnel Selection Procedures
When does a score mean the same thing across groups?
The question is not whether two versions of a questionnaire use the same words. It is whether the score supports the same comparison in the populations and conditions named. Measurement invariance means evidence that a measure’s structure and score meaning operate comparably across specified groups or occasions. It is investigated for a particular instrument, version, population, and comparison, not a certificate that every individual result has the same meaning. That distinction matters because a personality scale summarizes responses to items. If people in two groups understand an item differently, encounter different response conventions, or relate to the construct through different patterns, an observed average gap may reflect both actual trait differences and measurement differences. Identical wording controls one visible feature; it does not show that questions function alike or that the same score supports the same conclusion. The 2026 scoping review *Understanding and assessing personality across cultures: A scoping review* makes this problem concrete while limiting what can be concluded. It identified 233 publications and focused on English-language cross-cultural research published from 2004 through 2024. The review covered traits, characteristic adaptations, and life narratives, though most included publications used trait models. It reported that no reviewed instrument demonstrated full cross-cultural scalar invariance and cautioned against interpreting average personality-level differences across cultures. This finding concerns the literature it mapped, not every personality measure, every pair of cultures, or a particular reader’s report. That qualification matters. The review did not say all cross-cultural assessment is useless. It reported comparatively stronger validity and reliability evidence for the NEO Personality Inventory Revised and the 120-item International Personality Item Pool representation of that inventory. It also found some measures performed well within particular cultures. For the Schwartz values measure, it described acceptable psychometric properties and partial scalar invariance. Evidence can therefore be stronger for a named measure, construct, population, and comparison while remaining incomplete for another. Scalar invariance is especially relevant when the conclusion compares group averages. Researchers ask whether a response scale works comparably enough to interpret those averages as differences in the underlying construct rather than differences in item functioning or response patterns. The review’s caution is about average-level comparisons under the evidence it found. It does not establish that no other comparisons are possible, or that a particular individual feedback statement is useful. A report might support a tentative reflection prompt even when evidence does not support ranking group averages; these are different claims with different evidence needs. The *Standards for Educational and Psychological Testing* ties validity and fairness to interpretations, populations, settings, and intended uses. That framework supports asking whether evidence fits the conclusion. It does not provide invariance results for a named personality instrument. Readers should not convert it into a claim that a report passed a universal fairness test. The instrument’s own documentation and research must address the specific comparison. A practical check follows: if a report compares people across languages or cultural groups, look for evidence on the exact instrument version and comparison. Ask which groups were studied, whether research covered the same construct and language adaptation, and whether it supports average comparisons or narrower conclusions. If the report gives no basis, narrow its group-level language. Missing evidence does not prove bias, but identical wording and a familiar label do not fill the gap. Keep individual feedback provisional too: use it to generate a question about observable behavior, not a fixed description of identity. The conclusion can change when suitable evidence for that version, population, and comparison becomes available.
Sources: Understanding and assessing personality across cultures: A scoping review; Standards for Educational and Psychological Testing
Do group differences prove that an interpretation is unfair?
No. A difference between group averages is a reason to investigate the measure, sample, access conditions, and intended use. By itself, it cannot show whether the gap reflects variation in the measured tendency, a measurement problem, or both. Similar averages do not prove fair access or validate an individual interpretation.
The Standards for Educational and Psychological Testing says observed group differences should prompt scrutiny for possible bias, but do not alone establish that an application is biased or unfair. A provider cannot settle the issue by calling a difference a true trait gap; a reader cannot infer that the test caused it. The conclusion depends on the instrument, groups studied, and claim being made.
In employment selection, the Principles for the Validation and Use of Personnel Selection Procedures (fifth edition) distinguishes measurement bias from predictive bias. Measurement bias concerns irrelevant influences on scores that affect groups differently. Predictive bias asks whether scores relate differently to an employment outcome across subgroups. That differs from asking whether average scores differ. These concepts concern selection, not general personality reports.
Differential item functioning (DIF) is one possible item-level analysis: it asks whether people from different groups, matched on relevant measured standing, respond differently to an item. The Standards for Educational and Psychological Testing cautions that detecting DIF does not itself establish item bias; an explanation is needed. Limited subgroup evidence should narrow a conclusion, not assure that no problem exists.
A 2026 scoping review, Understanding and assessing personality across cultures: A scoping review, mapped English-language research from 2004 through 2024 covering personality constructs. It reported that none of the reviewed instruments showed full cross-cultural scalar invariance and cautioned against average-level cross-cultural comparisons. This concerns the literature and comparisons reviewed; it does not show every instrument fails for every group pair, that an individual report is unusable, or that a gap is necessarily bias. Its lesson is that group comparisons need evidence that the measure supports them.
The strongest alternative is that group averages differ because the measured tendency genuinely differs in the sampled groups. That is possible, but not established by the difference alone. Conversely, no detected average gap would not demonstrate equal access, rule out item-level problems, or validate an individual's report. Group comparisons and individual sentences answer different questions.
Ask whether evidence matches the precise claim: which instrument version and groups were studied, what analysis was used, and the conclusion being drawn. In selection, measurement and predictive evidence are separate questions. Without instrument-specific analysis and context, neither a true trait gap nor bias is established. Group differences trigger investigation; their meaning remains open until relevant evidence supports a narrower conclusion.
Sources: Principles for the Validation and Use of Personnel Selection Procedures; Understanding and assessing personality across cultures: A scoping review; Standards for Educational and Psychological Testing
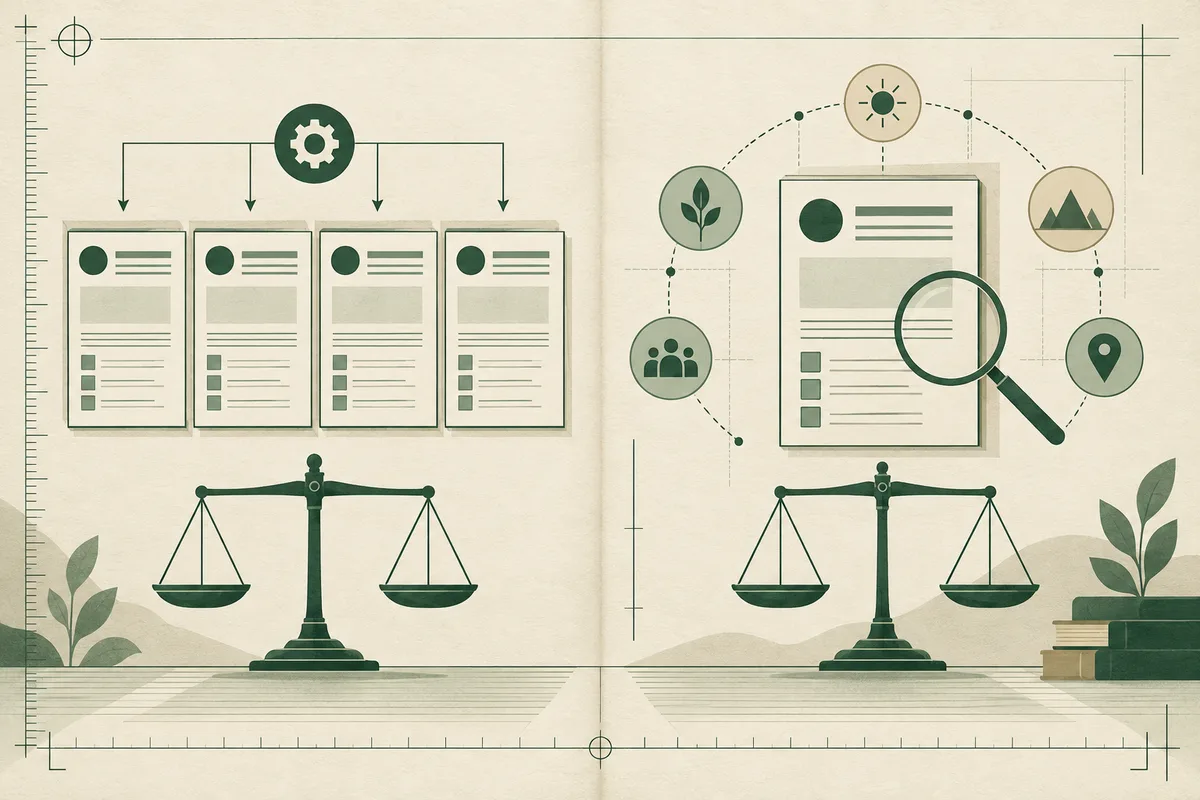
Why does the intended use change the fair conclusion?
A report's conclusion is only as strong as the use its evidence supports. A tentative self-reflection prompt may help someone notice a recurring tendency, provided the wording signals uncertainty. Coaching adds a question about when that tendency appears and what the person wants to change. Selection makes a different claim about using scores to choose among people. The same score does not carry the same warrant into each setting. This follows from what validity means. The Standards for Educational and Psychological Testing define validity in terms of evidence and theory supporting interpretations of scores for a given use. The standards call for evidence for each intended interpretation. Validity is therefore not a permanent badge attached to an instrument. Evidence for one reading does not automatically support every conclusion. For self-reflection, a sentence such as “You may prefer to plan before acting” can work as a prompt, not a finding about what someone always does. Its value can be explored through observable episodes: when did planning help, and when did waiting delay a decision? Examples, not the score alone, must ground the answer. Even here, uncertainty does not excuse absolute wording or an ill-fitting comparison group. Calling a tendency “your fixed style” goes beyond a cautious prompt, while a relative label such as “high” still needs a stated reference. Coaching changes the task. A report can suggest a topic, but choosing a goal calls for context: the situation, observable behavior, and outcome the person wants. A broad preference cannot explain a work difficulty or establish its cause. The report can be one source of questions alongside examples and other relevant information. Still, a personality score is not a diagnosis or forecast. Selection raises the evidentiary demand because the score may affect access to an opportunity. The Standards’ argument asks whether evidence supports the interpretation for its intended population and use. The Principles for the Validation and Use of Personnel Selection Procedures address employment selection specifically. They describe fairness perspectives that include equitable treatment and scrutiny of subgroup differences, and caution that no single statistical view exhausts fairness. They do not validate a general personality report for hiring; selection needs an argument tied to its decision and setting. There is a reasonable counterpoint: low-stakes use can still matter, and someone may find a description recognizable without technical documentation. Recognition can make a prompt worth considering; it cannot establish score precision, a fitting norm, or a stronger conclusion. Missing selection evidence does not make reflection pointless; it changes the responsible conclusion. The report may support a question to explore while remaining inadequate for ranking applicants. Name the decision before judging the report. If its evidence and wording support reflection, keep the claim there. If coaching is the goal, connect it to specific examples and an agreed question. If someone proposes using the score to select, promote, or make another consequential employment decision, ask for evidence tied to that purpose, population, criterion, and process. If unclear, pause that use. Equal procedures cannot make evidence travel automatically from one purpose to another.
Sources: Standards for Educational and Psychological Testing; Principles for the Validation and Use of Personnel Selection Procedures
How should a reader decide what one report sentence permits?
Take one sentence from a report and trace it backward. Ask what supports the statement, what comparison gives its score meaning, whether access or group-comparability evidence changes that meaning, and whether the evidence reaches the intended use. This trace applies distinctions in the Standards for Educational and Psychological Testing and the SIOP Principles; it is an editorial aid, not a validated method.
Consider this hypothetical sentence: “You tend to prefer clear plans before beginning a task.” First ask what the instrument intended to measure and how responses became a score or pattern. The report should identify the construct in understandable terms and explain how the result follows from responses. If unclear, ask for the scale description or scoring explanation; polished wording alone does not establish that scoring supports every phrase.
Next ask what makes the score interpretable. If the sentence rests on a comparison such as “higher than most,” the report should identify the reference group. A percentile describes a position within that distribution; it does not predict a behavior. The Standards for Educational and Psychological Testing treats validity as evidence for an interpretation and use, while reliability and measurement error matter to score precision. If the report omits applicable norm information or uncertainty, keep the sentence tentative rather than treating a rank or boundary as exact.
Then consider access and comparability. Could an interface, language, or response format have added a demand unrelated to the intended tendency? Does evidence cover the version and comparison at issue? The 2026 cross-cultural scoping review reports that none of its reviewed instruments had full cross-cultural scalar invariance, although some measures had comparatively stronger evidence. This does not determine an individual result, but shows why identical wording alone cannot establish a broad group comparison. Missing evidence about a relevant adaptation or comparison is a reason to narrow the claim or ask the provider what applies, not to declare the measure unusable.
Finally, name the use. “This may be a prompt for noticing how you start work” is a limited self-reflection statement. “This proves you will perform well in a role requiring planning” is a stronger claim. The SIOP Principles address personnel selection and distinguish score measurement from prediction of work outcomes. They cannot validate an unspecified instrument or carry a reflective description into selection. Recognition may make the sentence worth discussing, but does not repair an unclear norm, establish comparable access, or validate a prediction.
If one link is missing, qualify the sentence instead of treating the whole report as proven or worthless. Identify the wording and request the information that could change its interpretation: scoring basis, comparison and uncertainty, evidence for an adaptation or group comparison, or support for the intended use. If those details remain unavailable, use the statement as a question to test against observable experience, not as a fixed label or decision rule. This preserves what the report may help the reader notice while respecting what its evidence has not shown.
Sources: Standards for Educational and Psychological Testing; Principles for the Validation and Use of Personnel Selection Procedures; Understanding and assessing personality across cultures: A scoping review
What is the fairest next step when the evidence is incomplete?
Keep a report’s conclusion at the narrowest level its evidence supports. Equal treatment protects consistent procedures; fair interpretation asks whether access, comparison, and intended use justify the sentence. The Standards for Educational and Psychological Testing treats validity as support for score interpretations and uses, so consistent scoring alone cannot support a stronger conclusion. For private reflection, test one tentative description against a recent example and an example that complicates it. If both fit only in certain settings, keep that condition in view rather than turning a tendency into a fixed label. Recognition can make a prompt useful, but it cannot supply missing norm evidence or prove a claim. For a consequential decision, ask the provider for evidence tied to the instrument, population, comparison, and purpose. If the score is used beyond its supported purpose, pause until the gap is clarified. Uncertainty should narrow the action, not invite a verdict about the person. If the question concerns a work or collaboration pattern, the live Work Pattern Report can offer low-stakes self-reflection. It supplies no norm, cutoff, hiring score, or job recommendation, and cannot establish whether another assessment is fair. For other report questions, see the publication’s assessment-literacy guides.
Sources: Standards for Educational and Psychological Testing
Questions readers ask
Does equal treatment mean every reader must take a personality assessment in exactly the same way?
No. A different access route may remove a barrier while preserving the intended measurement. Whether an adjustment preserves score meaning depends on the instrument and the specific change; ask the provider for evidence when that is unclear.
Does a difference between group averages prove that a personality test is biased?
No. A group difference calls for examination of the measure, sample, access conditions, and intended use. It does not by itself establish bias or prove that the difference reflects only the measured tendency.
Can a personality report support a hiring or job-fit decision?
A general personality report does not, by itself, establish job fit or support a selection decision. Consequential use needs evidence tied to the instrument, population, comparison, and purpose.
Sources and notes
- Standards for Educational and Psychological Testing
Supports distinctions among validity for interpretations and uses, fairness, access, scoring, and measurement error.
- Code of Fair Testing Practices in Education
Supports the broad professional responsibility to consider fairness across testing practices and personal characteristics.
- Realizing Fairness Through Accessibility for All Test Takers and for Specific Groups
Provides an educational-assessment framework for access to the measured construct; it does not directly address personality tests.
- Principles for the Validation and Use of Personnel Selection Procedures
Supports selection-context distinctions among fairness perspectives, measurement bias, predictive bias, and subgroup score differences.
- Understanding and assessing personality across cultures: A scoping review
Reports the review’s cross-cultural personality measurement findings and cautions about average-level comparisons within its reviewed literature.
- Guides | Personality Report
Shows the publication’s existing coverage of the question and adjacent guides on accommodations and subgroup validity.
Apply it to your work
Turn a broad work pattern into a question you can examine
From this guide: If the report leaves you wondering how a tendency shows up in a specific work or collaboration pattern, start with observations from your own experience.
A personality report can suggest a question, but it cannot settle what causes recurring work friction or how a tendency appears in every situation. The Work Pattern Report offers a low-stakes way to reflect on decision, planning, collaboration, conflict, and learning tendencies. Use its observations as prompts to compare with your experience, not as a normed score, job recommendation, or employment decision.